The Open Weights
LatestModelsLeaderboardsCompanies
Subscribe
The Open Weights

The daily record of open-source AI. New model releases, leaderboards, and what's coming next — written for people who ship.

Refreshed every 12 hours

Discover

  • Latest releases
  • New today
  • Trending models

Browse

  • All models
  • Companies
  • Categories
  • Leaderboards

About

  • About
  • Editorial policy
  • Hardware estimates
  • RSS feed
  • llms.txt
  • Newsletter

© 2026 The Open Weights. An independent publication.

PrivacyTermsSMSAggregated by Claude · curated by humans.

Chronological

Release timeline

Every open-weight model release we've tracked, day by day — scroll the full chronology of open-source AI, from today's drops back through the year.

Monday, October 26, 2026

1 release

Baidu/Vision-LanguageRuns anywhere

Baidu releases Unlimited-OCR 2 under MIT license

The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Oct 26, 2026
Vision-Language
Unlimited-OCR 2
Saturday, October 24, 2026

1 release

Nanbeige/Text / LLMConsumer GPU

Nanbeige 4.3 Arrives as a 33B Bilingual Model

A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.

Oct 24, 2026
Text / LLM
Nanbeige4.3-33B
Friday, October 23, 2026

1 release

LiquidAI/Text / LLMRuns anywhere

Liquid AI debuts LFM3-1.7B for edge deployment

A compact 1.7B-parameter multilingual model built to run locally and serve as the base for specialized multimodal variants.

Oct 23, 2026
Text / LLM
LFM3-1.7B
Wednesday, October 21, 2026

3 releases

IBM/Speech → Text

IBM's Granite Speech 5.0 Adds Speaker Attribution

The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.

Oct 21, 2026
Speech → Text
RecursiveSI/Text / LLMConsumer GPU

Recursive releases Flint, an Apache-2.0 chat model

The new conversational LLM ships under a permissive license with community GGUF builds already available for local use.

Oct 21, 2026
Text / LLM
Flint
KRAFTON/Text / LLMConsumer GPU

KRAFTON releases Raon-1-mini preview under Apache 2.0

The Korean game studio behind PUBG puts out a compact, permissively licensed language model as an early preview.

Oct 21, 2026
Text / LLM
Raon-1-mini (preview)
Monday, October 19, 2026

1 release

Qwen · Alibaba/Speech → Text

Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription

Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Oct 19, 2026
Speech → Text
Sunday, October 18, 2026

1 release

Briaai/Text → ImageRuns on a laptop

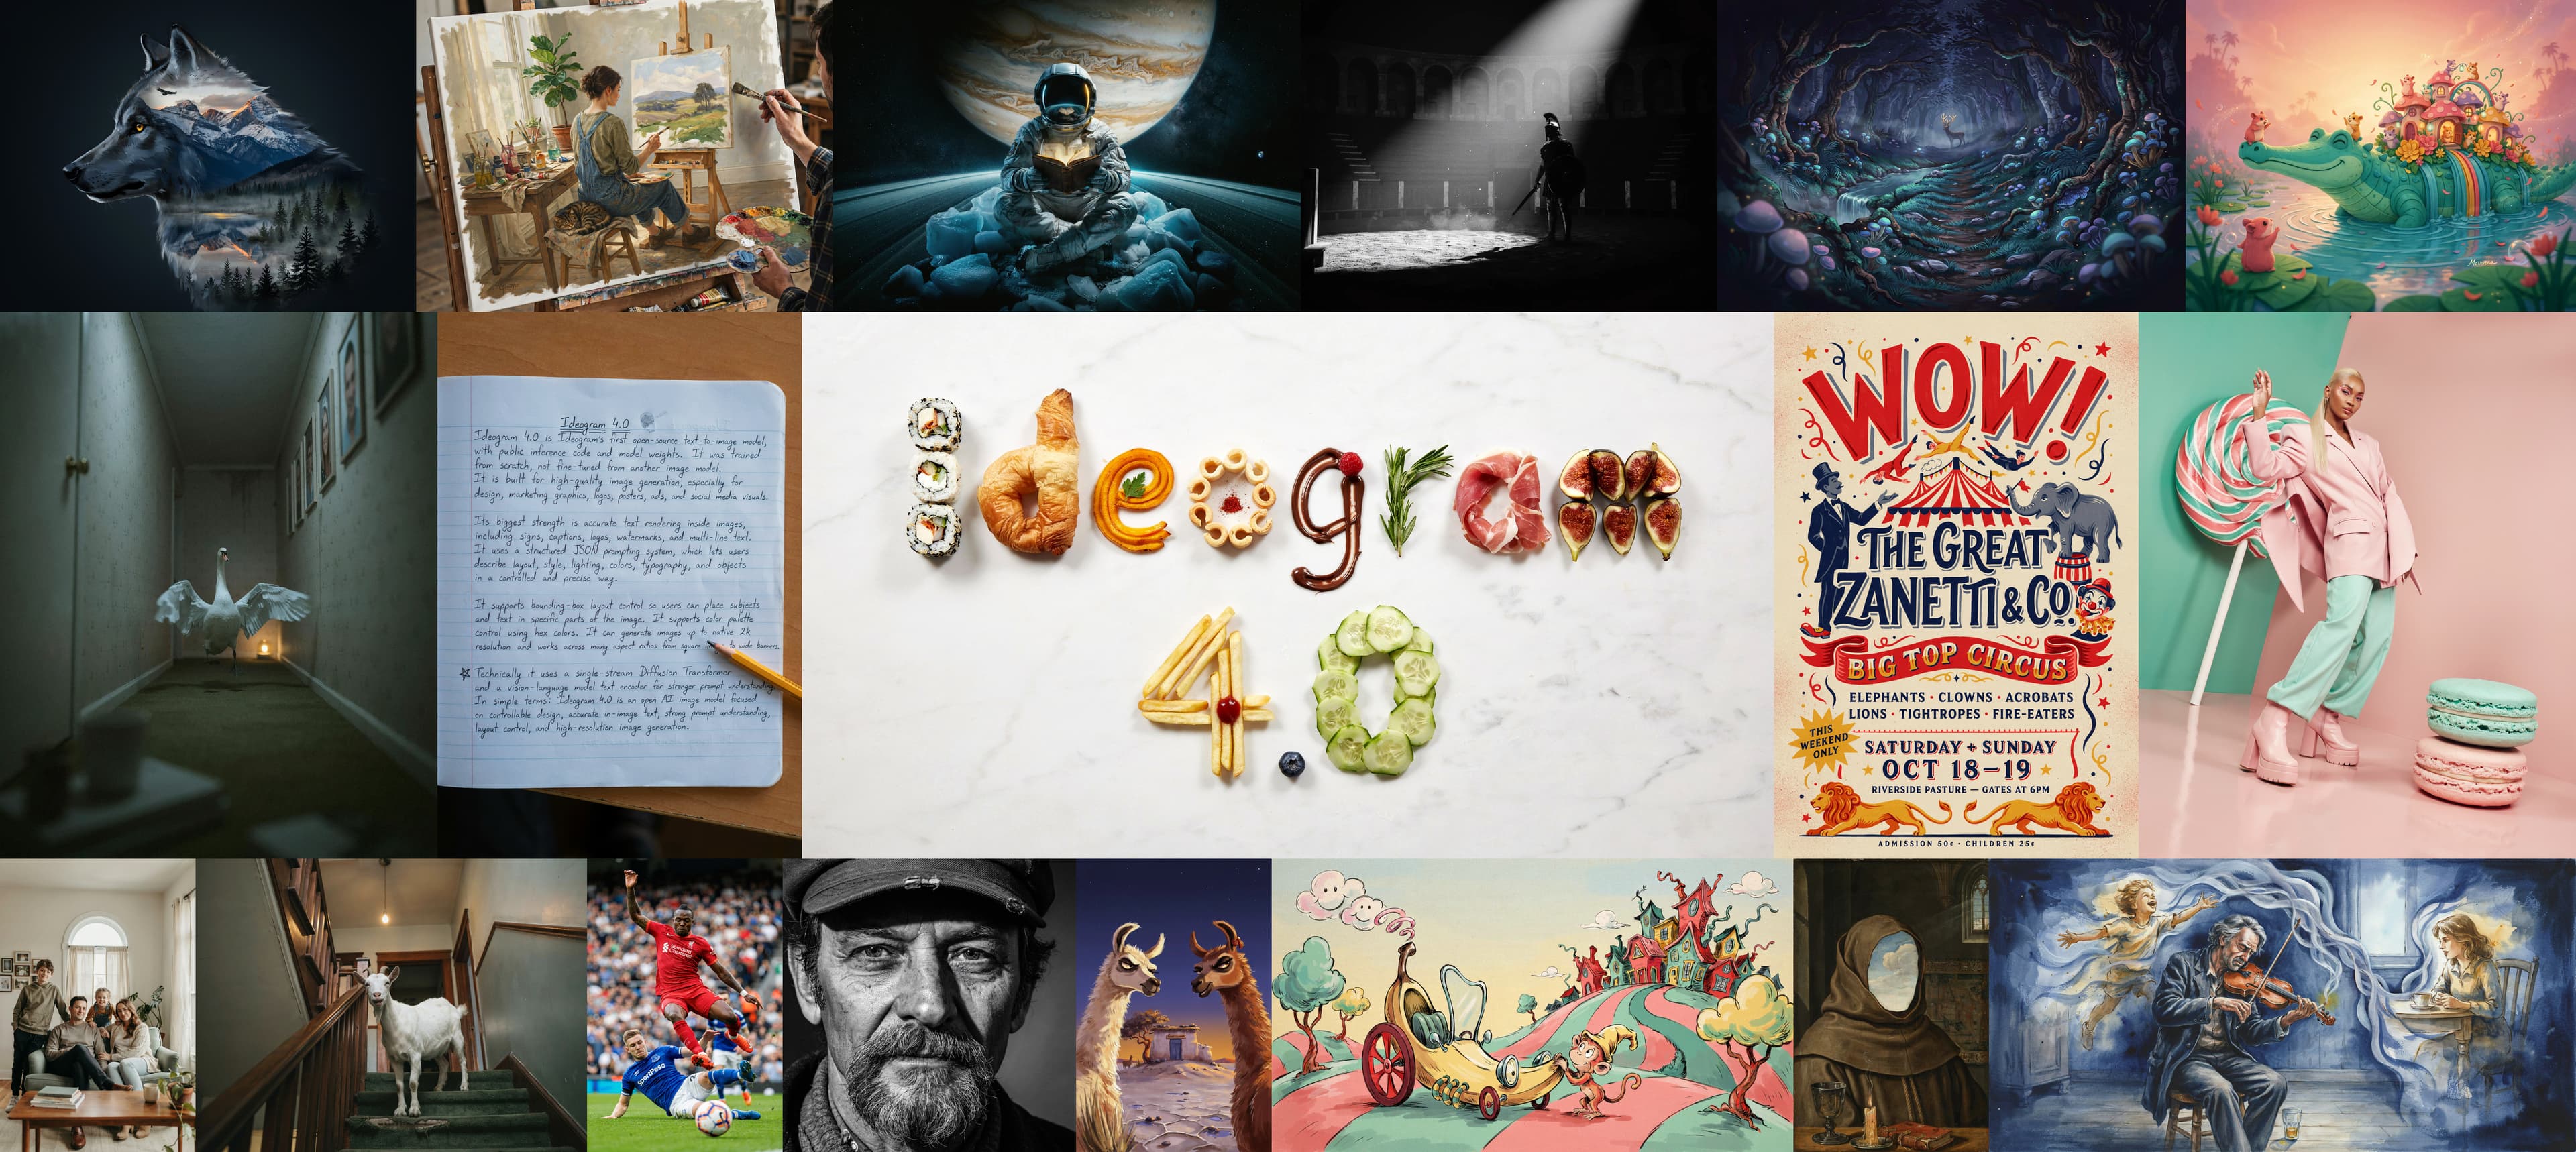
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI

The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Oct 18, 2026
Text → ImageImage Editing
Fibo 2.0-dev
Saturday, October 17, 2026

2 releases

MiniMax/Vision-LanguageMulti-GPU server

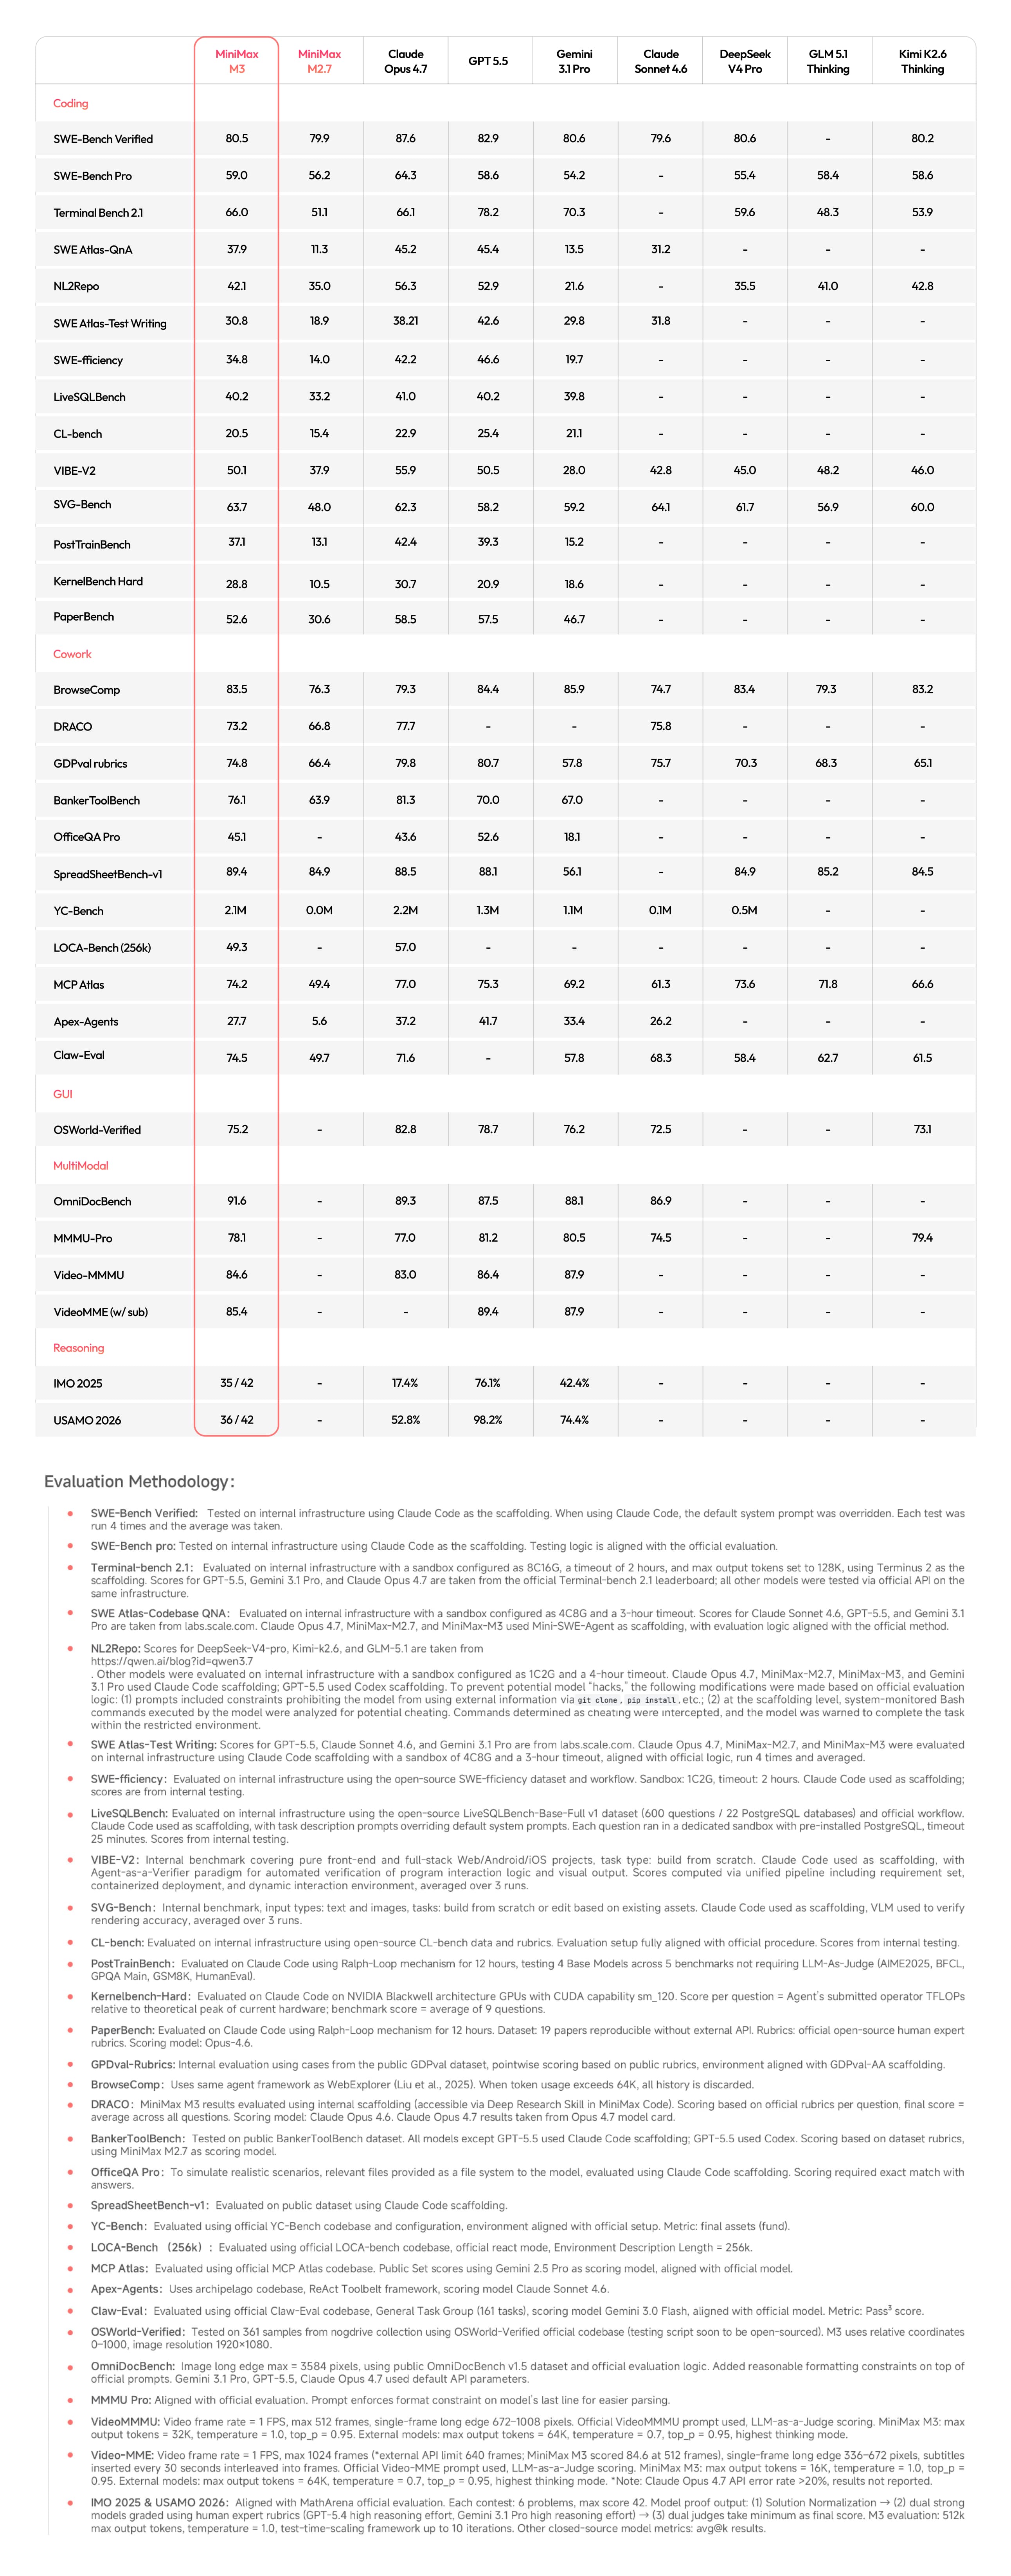
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model

The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

Oct 17, 2026
Vision-LanguageCode
MiniMax-M3.1-Flash
DeepSeek/Vision-LanguageMajor releaseDatacenter

DeepSeek V4.1-Flash Adds Vision and Reasoning

The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.

Oct 17, 2026
Vision-LanguageText / LLM
DeepSeek-V4.1-Flash (1017)
Friday, October 16, 2026

2 releases

NVIDIA/Text / LLMRuns on a laptop

NVIDIA releases compact Dory 1.0 4B text model

The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.

Oct 16, 2026
Text / LLM
Nemotron Labs Dory 1.0 4B
Ornith Ai/Text / LLMWorkstation GPU

Ornith AI releases 122B MoE multimodal model under MIT

The Qwen3.5-based Ornith-1.5 pairs a mixture-of-experts design with vision support and an unusually permissive license.

Oct 16, 2026
Text / LLMVision-Language
Ornith-1.5-122B
Thursday, October 15, 2026

4 releases

IBM/Any-to-Any

IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech

A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.

Oct 15, 2026
Any-to-AnyText / LLM
Meta AI/Any-to-AnyMajor release

Meta's Muse Spark Open Targets Agentic Coding

The new open-weight model pairs a million-token context window with Meta's bet on long-horizon coding agents.

Oct 15, 2026
CodeText / LLM
Tencent/Text / LLMConsumer GPU

Tencent releases Hy-Memory 30B-A3B under Apache 2.0

A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.

Oct 15, 2026
Text / LLM
Hy-Memory 30B-A3B
InternScience/Vision-LanguageConsumer GPU

Sage-A1.5 Brings Agentic Vision to Open MoE Models

InclusionAI's new mixture-of-experts model pairs visual understanding with tool use and code, aiming at agentic workflows under an Apache 2.0 license.

Oct 15, 2026
Vision-LanguageReasoning
Sage-A1.5
Wednesday, October 14, 2026

1 release

Mistral AI/Text / LLMRuns anywhere

Mistral's Timestral brings forecasting to open weights

The French lab releases a compact 209M-parameter foundation model aimed squarely at time-series prediction.

Oct 14, 2026
Text / LLM
Timestral-209M
Tuesday, October 13, 2026

2 releases

inclusionAI/Text / LLMDatacenter

inclusionAI releases Ling-3.1-flash under MIT license

A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.

Oct 13, 2026
Text / LLM
Ling-3.1-flash
Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

Black Forest Labs ships FLUX.3 Image Klein

The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.

Oct 13, 2026
Text → ImageImage Editing
FLUX.3 Image Klein
Monday, October 12, 2026

3 releases

NVIDIA/Vision-LanguageWorkstation GPU

NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency

The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.

Oct 12, 2026
Vision-LanguageText / LLM
Nemotron-3.5-Super-VL-120B-A12B
NVIDIA/Vision-LanguageWorkstation GPU

NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE

The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.

Oct 12, 2026
Vision-LanguageText / LLM
Nemotron-3.5-Super-VL-120B-A12B
LiquidAI/EmbeddingsConsumer GPU

Liquid AI's LFM2.5 Puts a 24B MoE on Your Device

The new mixture-of-experts model keeps total capacity high while activating only about 2B parameters per token for edge agents.

Oct 12, 2026
Text / LLM
LFM2.5-24B-A2B
Sunday, October 11, 2026

2 releases

OpenMOSS/Text → ImageRuns on a laptop

OpenMOSS Releases MOSS-Image Under Apache 2.0

The academic team behind the MOSS project moves into text-to-image generation with a permissively licensed model and a fine-tuned SFT variant.

Oct 11, 2026
Text → Image
MOSS-Image SFT
OpenMOSS/Text → ImageRuns on a laptop

OpenMOSS Releases Apache-2.0 Bilingual Image Model

MOSS-Image Base arrives as a permissively licensed text-to-image foundation with English and Chinese support.

Oct 11, 2026
Text → Image
MOSS-Image SFT
Saturday, October 10, 2026

1 release

Datalab To/Vision-LanguageRuns anywhere

Indra OCR brings CPU-friendly document parsing

A new open vision-language model targets layout, handwriting and multilingual text extraction without a GPU.

Oct 10, 2026
Vision-Language
Indra OCR
Friday, October 9, 2026

2 releases

Tencent/Vision-LanguageRuns on a laptop

Tencent's Youtu-Parsing-Omni tackles docs, audio, video

A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.

Oct 9, 2026
Vision-LanguageAny-to-Any
Youtu-Parsing-Omni
Qwen · Alibaba/Text → ImageRuns on a laptop

Qwen-Image-2.1-Turbo targets faster generation

Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Oct 9, 2026
Text → ImageImage Editing
Qwen-Image-2.1-Turbo
Wednesday, October 7, 2026

7 releases

Xiaomi/Vision-Language

Xiaomi's MiMo-V2.6 bets on RL for self-improvement

The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.

Oct 7, 2026
ReasoningAny-to-Any
Reflection/ReasoningMajor releaseMulti-GPU server

Reflection releases Beam 1.0, a 501B open MoE

The frontier AI startup's first open-weight model activates just 23B parameters per token while targeting reasoning, code, and tool use.

Oct 7, 2026
ReasoningText / LLM
Beam 1.0 501B-A23B
NVIDIA/Vision-LanguageWorkstation GPU

NVIDIA's Nemotron-3.5 Bolt targets 24GB GPUs

A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.

Oct 7, 2026
Vision-LanguageText / LLM
Nemotron-3.5 Bolt 74B-A9B
LiquidAI/Vision-LanguageRuns anywhere

Liquid AI's d1-3B brings multimodal models to the edge

The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.

Oct 7, 2026
Vision-Language
LFM2 d1-3B
IBM/Speech → Text

TII extends the Falcon family into speech recognition

The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.

Oct 7, 2026
Speech → Text
NVIDIA/Speech → Text

TII Brings Falcon to Speech With New ASR Model

The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.

Oct 7, 2026
Speech → Text
OpenBMB/Vision-LanguageConsumer GPU

OpenBMB's MiniCPM-V 4.7 brings MoE to vision models

The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.

Oct 7, 2026
Vision-Language
MiniCPM-V 4.7 35B-A3B
Tuesday, October 6, 2026

4 releases

Mistral AI/Text / LLMMajor releaseDatacenter

Mistral Large 4 arrives as a trillion-param MoE

The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.

Oct 6, 2026
Text / LLMReasoning
OpenBMB/Vision-LanguageConsumer GPU

MiniCPM-V 4.7 brings a 35B MoE vision model on-device

OpenBMB's latest multimodal release activates just 3B parameters per token, aiming to keep capable image understanding local.

Oct 6, 2026
Vision-Language
MiniCPM-V 4.7 35B-A3B
LightOn/Vision-LanguageRuns on a laptop

LightOn ships a 4B OCR model with visual grounding

LightOnOCR-3-4B pairs document transcription with the ability to point back to where text sits on the page.

Oct 6, 2026
Vision-Language
LightOnOCR-3-4B
NVIDIA/Text / LLM

Falcon-Emirati tunes an LLM for local dialect

TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.

Oct 6, 2026
Text / LLM
Monday, October 5, 2026

3 releases

Reflection AI/Text / LLMMulti-GPU server

Reflection AI debuts Beam, a 501B open model

The startup's first open-weight release is a dense 501-billion-parameter model aimed at text and reasoning tasks.

Oct 5, 2026
Text / LLMReasoning
OpenAI/Text / LLMMajor releaseMulti-GPU server

Reflection releases Beam, a 501B open-weight model

The startup's first frontier-scale model ships with downloadable weights and a mixture-of-experts design aimed at reasoning.

Oct 5, 2026
Text / LLMReasoning
NVIDIA/Text / LLMRuns on a laptop

NVIDIA's Nemotron 3.5 Bolt Targets 4GB Devices

The compact 4-billion-parameter text model is tuned for multilingual work on memory-constrained hardware.

Oct 5, 2026
Text / LLM
Nemotron 3.5 Bolt E4B
Saturday, October 3, 2026

4 releases

Unknown/Text → VideoConsumer GPU

Kandinsky 6.0 Generates Video and Audio Together

Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.

Oct 3, 2026
Text → Video
Aleph Alpha/Text / LLM

Aleph Alpha releases Kolibri, a sovereign open model

The German AI firm positions its new open-weight language model as a European alternative built with digital sovereignty in mind.

Oct 3, 2026
Text / LLM
IBM/Text / LLM

Aleph Alpha releases Kolibri, a sovereign open model

The German AI lab frames its new open-weight language model around European data sovereignty and transparency.

Oct 3, 2026
Text / LLM
OpenAI/Text / LLM

Aleph Alpha launches Kolibri, a sovereign open model

The German AI firm positions its new open-weight language model as a European alternative built for data control and compliance.

Oct 3, 2026
Text / LLM
Friday, October 2, 2026

2 releases

Allen Institute for AI/Text / LLM

Allen Institute Open-Sources AstaBrief Report Model

The fast report-generation model behind AI2's Asta research assistant is now available under an Apache 2.0 license.

Oct 2, 2026
Text / LLM
Aleph Alpha/ReasoningWorkstation GPU

Aleph Alpha releases Kolibri, a sovereign reasoning model

The German AI company's open-weight mixture-of-experts model targets European needs with strong German and English reasoning.

Oct 2, 2026
ReasoningText / LLM
Kolibri-1
Thursday, October 1, 2026

3 releases

Perplexity Ai/Vision-LanguageConsumer GPU

Perplexity releases a 27B model for multimodal routing

The open-weight 'decider' model is designed to classify queries and route them inside Perplexity's stack.

Oct 1, 2026
Vision-Language
pplx-decider-v1-27b
Cloudflare/Vision-LanguageConsumer GPU

Cloudflare's Clef brings structured decisions to open models

The new open-weight vision-language family outputs typed, structured results and arrives alongside a reinforcement-learning fine-tuning platform.

Oct 1, 2026
Vision-LanguageAny-to-Any
Clef
Fishaudio/Text → SpeechWorkstation GPU

Fish Audio's Drama 3 brings MoE to open TTS

The open-source speech model pairs a 35B mixture-of-experts backbone with voice cloning and directed performance control.

Oct 1, 2026
Text → Speech
Fish Audio Drama 3
Wednesday, September 30, 2026

2 releases

Cactus Compute/Speech → Text

Cactus Compute's Whistle brings speech-to-text to the edge

A compact on-device ASR model built for edge hardware and WebAssembly, with early support for English, German, and French.

Sep 30, 2026
Speech → Text
Whistle
Autotrust/Vision-LanguageConsumer GPU

JEV-27B-VL Pairs Vision-Language With Calibrated Odds

A 27B vision-language model from autotrust aims to output typed decisions with probabilities you can actually trust.

Sep 30, 2026
Vision-Language
JEV-27B-VL
Tuesday, September 29, 2026

1 release

BAAI/ReasoningConsumer GPU

AREX-2 arrives as an open deep-research agent model

The reasoning-focused release pairs tool use with long context and self-improvement, and ships as a vision-language model on Hugging Face.

Sep 29, 2026
ReasoningVision-Language
AREX-2
Monday, September 28, 2026

3 releases

FermionResearch/Speech → TextRuns anywhere

Phonon-2 brings on-device ASR to Apple Silicon

A low-bit quantized, Parakeet-based speech recognizer built to run locally on Mac hardware.

Sep 28, 2026
Speech → Text
Phonon-2
OpenAI/Vision-Language

H Company releases Holo4 for computer-use agents

The new vision-language model is built to drive generalist agents that operate real software interfaces.

Sep 28, 2026
Vision-Language
H company/Vision-Language

H Company's Holo4 Takes On Computer-Use Agents

The French startup's new vision-language model is built to see and operate software the way a person would.

Sep 28, 2026
Vision-Language
Thursday, September 24, 2026

2 releases

Unknown/Vision-Language

Liquid AI's LFM2.5-VL-DSpark targets faster VLM inference

The new vision-language model from Liquid AI is tuned for accelerated inference, extending the company's LFM2 line into multimodal territory.

Sep 24, 2026
Vision-Language
FrancisRing/Image → Video

Prism Brings Joint Video-Audio Generation to Diffusion

A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.

Sep 24, 2026
Image → Video
Prism
Wednesday, September 23, 2026

1 release

Fastino/Text / LLMRuns anywhere

Fastino's GLiNER2.5-Decide targets lean NLP tasks

A sub-1B model bundling entity extraction, intent, sentiment and topic classification arrives on Hugging Face.

Sep 23, 2026
Text / LLM
GLiNER2.5-Decide
Tuesday, September 22, 2026

1 release

Black Forest Labs/Any-to-Any

Black Forest Labs brings FLUX to robotics

The image-model maker's FLUX 3 Action Base extends its generative stack into world-action modeling, released through the LeRobot ecosystem.

Sep 22, 2026
Any-to-Any
FLUX 3 Action Base
Monday, September 21, 2026

5 releases

Xiaomi/Vision-LanguageRuns on a laptop

Xiaomi distills MiMo V2.6 into a 9B model

The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.

Sep 21, 2026
Vision-LanguageText / LLM
MiMo-V2.6
Apple/Vision-LanguageRuns on a laptop

Apple's LensVLM-9B targets long-context vision tasks

A 9-billion-parameter vision-language model built on Qwen3.5-9B leans on visual-text compression to stretch its usable context.

Sep 21, 2026
Vision-Language
LensVLM-9B
Xiaomi/Any-to-AnyMulti-GPU server

Xiaomi expands MiMo line with V2.6 multimodal models

The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.

Sep 21, 2026
Any-to-AnyVision-Language
MiMo-V2.6 (Flash/Pro
Xiaomi/Vision-LanguageDatacenter

Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work

An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.

Sep 21, 2026
Vision-LanguageText / LLM
MiMo-V2.6-Pro-RL
Edge0/Speech → TextRuns on a laptop

Audio8-ASR-Infinite brings streaming bilingual speech recognition

A new open model targets real-time transcription for Chinese and English audio.

Sep 21, 2026
Speech → Text
Audio8-ASR-Infinite
Sunday, September 20, 2026

2 releases

JetBrains/CodeRuns on a laptop

JetBrains ships Mellum 2.1, a reasoning MoE for code

The updated Mellum packs 12B total parameters but activates just 2.5B, pairing code specialization with a new thinking mode under Apache-2.0.

Sep 20, 2026
CodeReasoning
Mellum2.1-12B-A2.5B-Thinking
StepFun/Vision-LanguageDatacenter

StepFun Posts Step-5-Preview Vision-Language Model

The Chinese AI lab's early look at its next multimodal system arrives on Hugging Face ahead of a full release.

Sep 20, 2026
Vision-LanguageText / LLM
Step-5-Preview
Friday, September 18, 2026

2 releases

moondream/Speech → TextRuns anywhere

Moondream shrinks Parakeet ASR for CPUs

A ternary-quantized take on the Parakeet TDT speech model aims to run transcription without a GPU.

Sep 18, 2026
Speech → Text
Parakeet Redux
Convaiinnovations/Text / LLMRuns anywhere

Convai's Laya targets fast AI decisions and guardrails

A new "System-One" model from Convai Innovations focuses on routing, scoring and safety checks rather than open-ended generation.

Sep 18, 2026
Text / LLM
Laya (System-One)
Thursday, September 17, 2026

2 releases

inclusionAI/Text → ImageRuns on a laptop

inclusionAI's Ming-Image targets graphic design

A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.

Sep 17, 2026
Text → Image
Ming-Image-0.1-Design
Microsoft/Text / LLMRuns on a laptop

Microsoft Releases FrogNano-4B Under MIT License

The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.

Sep 17, 2026
Text / LLM
FrogNano-4B
Wednesday, September 16, 2026

4 releases

Prism Ml/Text / LLMConsumer GPU

Ternary-Bonsai-2 packs a 27B model into 2-bit form

A ternary-quantized 27B model with hybrid attention targets on-device inference across CUDA and Metal.

Sep 16, 2026
Text / LLM
Ternary-Bonsai-2-27B
Ukisai/ReasoningConsumer GPU

Swift-1.5 Trims Reasoning Tokens on a 27B Qwen Model

XingChen-AGI's new tune aims to make Qwen3.8-27B reason faster by cutting its thinking budget roughly in half.

Sep 16, 2026
ReasoningVision-Language
Swift-1.5-Qwen3.8-27B
XingChen AGI/Text / LLMConsumer GPU

Xing4.0 arrives as a 29B MoE with 4B active params

inclusionAI's new text model uses a mixture-of-experts design to keep compute low while shipping under an Apache-2.0 license.

Sep 16, 2026
Text / LLM
Xing4.0-29B-A4B
Cactus Compute/Text / LLM

Cactus Needle 3: tiny on-device tool-calling models

Cactus Compute's 8–29MB models aim to run automation and tool-calling entirely on-device, rivaling far larger cloud systems.

Sep 16, 2026
Text / LLMCode
Cactus Needle 3
Tuesday, September 15, 2026

1 release

Meta AI/Any-to-AnyMajor releaseDatacenter

Meta's Muse Spark Open brings a frontier MoE to open weights

The 816B-parameter mixture-of-experts model activates just 42B per token and targets agentic coding across a million-token context.

Sep 15, 2026
Any-to-AnyText / LLM
Muse Spark Open
Monday, September 14, 2026

3 releases

Unknown/Text → Speech

Nari Labs Ships Qwen3-Based TTS and ASR Models

The startup pairs speech synthesis and recognition built on Qwen3, pitching accuracy, low latency, and lower cost.

Sep 14, 2026
Text → SpeechSpeech → Text
Google DeepMind/EmbeddingsRuns anywhere

EmbeddingGemma 2 Expands to Any Modality

Google DeepMind's compact embedding model now spans text, vision, audio, and video in a single vector space.

Sep 14, 2026
EmbeddingsAny-to-Any
EmbeddingGemma 2
Qwen · Alibaba/Text → ImageRuns on a laptop

Qwen-Image-2.1 Adds RGBA to Image Generation

Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.

Sep 14, 2026
Text → ImageImage Editing
Qwen-Image-2.1
Saturday, September 12, 2026

1 release

Yandex/Text / LLMWorkstation GPU

Yandex releases 80B MoE base model under Apache 2.0

AliceAI-Foundation is a sparse mixture-of-experts model with just 3B active parameters, aimed at Russian and English text.

Sep 12, 2026
Text / LLM
AliceAI-Foundation-80B-A3B-Base
Friday, September 11, 2026

3 releases

StepFun/Text → Speech

StepFun's StepAudio 3 Realtime targets live voice AI

The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.

Sep 11, 2026
Text → SpeechSpeech → Text
Agnes AI/Vision-LanguageConsumer GPU

Agnes-3.0-Flash arrives as a multimodal reasoning model

The new release pairs vision-language understanding with a hybrid-attention design aimed at long-context reasoning.

Sep 11, 2026
Vision-LanguageReasoning
Agnes-3.0-Flash
Internlm/ReasoningDatacenter

InternLM's Atria Dawn Preview Targets Agentic Tasks

A new mixture-of-experts model trained on verified tool interactions arrives as an early preview under an MIT license.

Sep 11, 2026
ReasoningText / LLM
Atria Dawn Preview
Thursday, September 10, 2026

6 releases

Unknown/ReasoningRuns on a laptop

ZGCM-1 arrives as a fully open 7B reasoning model

A compact foundation model targets math reasoning and agentic search with tool use, and its makers are releasing it fully open.

Sep 10, 2026
ReasoningText / LLM
StepFun/Text → Speech

StepFun's StepAudio 3 Gen Unifies TTS and Music

A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.

Sep 10, 2026
Text → SpeechMusic
StepFun/Music

StepFun's StepAudio 3 Music Plans Before It Plays

The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.

Sep 10, 2026
Music
Yandex/Text / LLMConsumer GPU

Yandex releases a sparse T5 model with 0.6B active params

The AliceAI-T5-35B-A0.6B is an encoder-decoder mixture-of-experts model that keeps only a sliver of its 35B parameters active per token.

Sep 10, 2026
Text / LLM
AliceAI-T5-35B-A0.6B
Netease Youdao/Speech → TextRuns anywhere

NetEase Youdao debuts Confucius4-R2T2 streaming ASR

The multilingual speech-to-text model targets low latency and ships with vLLM support for production deployments.

Sep 10, 2026
Speech → Text
Confucius4-R2T2
Mrfakename/MusicRuns on a laptop

OpenMOSS Unveils YuE2-3B Music Generation Model

The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.

Sep 10, 2026
Music
YuE2-3B
Wednesday, September 9, 2026

3 releases

Tencent/ReasoningWorkstation GPU

Tencent's T1 Targets Long-Horizon Terminal Work

A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.

Sep 9, 2026
ReasoningCode
SenseTime/Any-to-AnyRuns on a laptop

SenseTime's SenseNova-U1.5 Unifies Vision Tasks

An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.

Sep 9, 2026
Any-to-AnyVision-Language
M A P/MusicRuns on a laptop

OpenMOSS releases YuE2-3B for music generation

The 3-billion-parameter model pairs symbolic planning with agentic editing to generate and refine full songs in English and Chinese.

Sep 9, 2026
Music
YuE2-3B
Tuesday, September 8, 2026

4 releases

inclusionAI/Vision-LanguageRuns on a laptop

LLaDA-UI Brings Diffusion Decoding to GUI Agents

inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.

Sep 8, 2026
Vision-Language
Edge0/Text / LLMConsumer GPU

Edge0's 35B MoE Aims for SSD-Backed Edge Inference

A preview mixture-of-experts model uses trained routing prediction to run on machines that can't hold it all in memory.

Sep 8, 2026
Text / LLM
Edge0-35B-A3B-preview
Nex Agi/Vision-LanguageMulti-GPU server

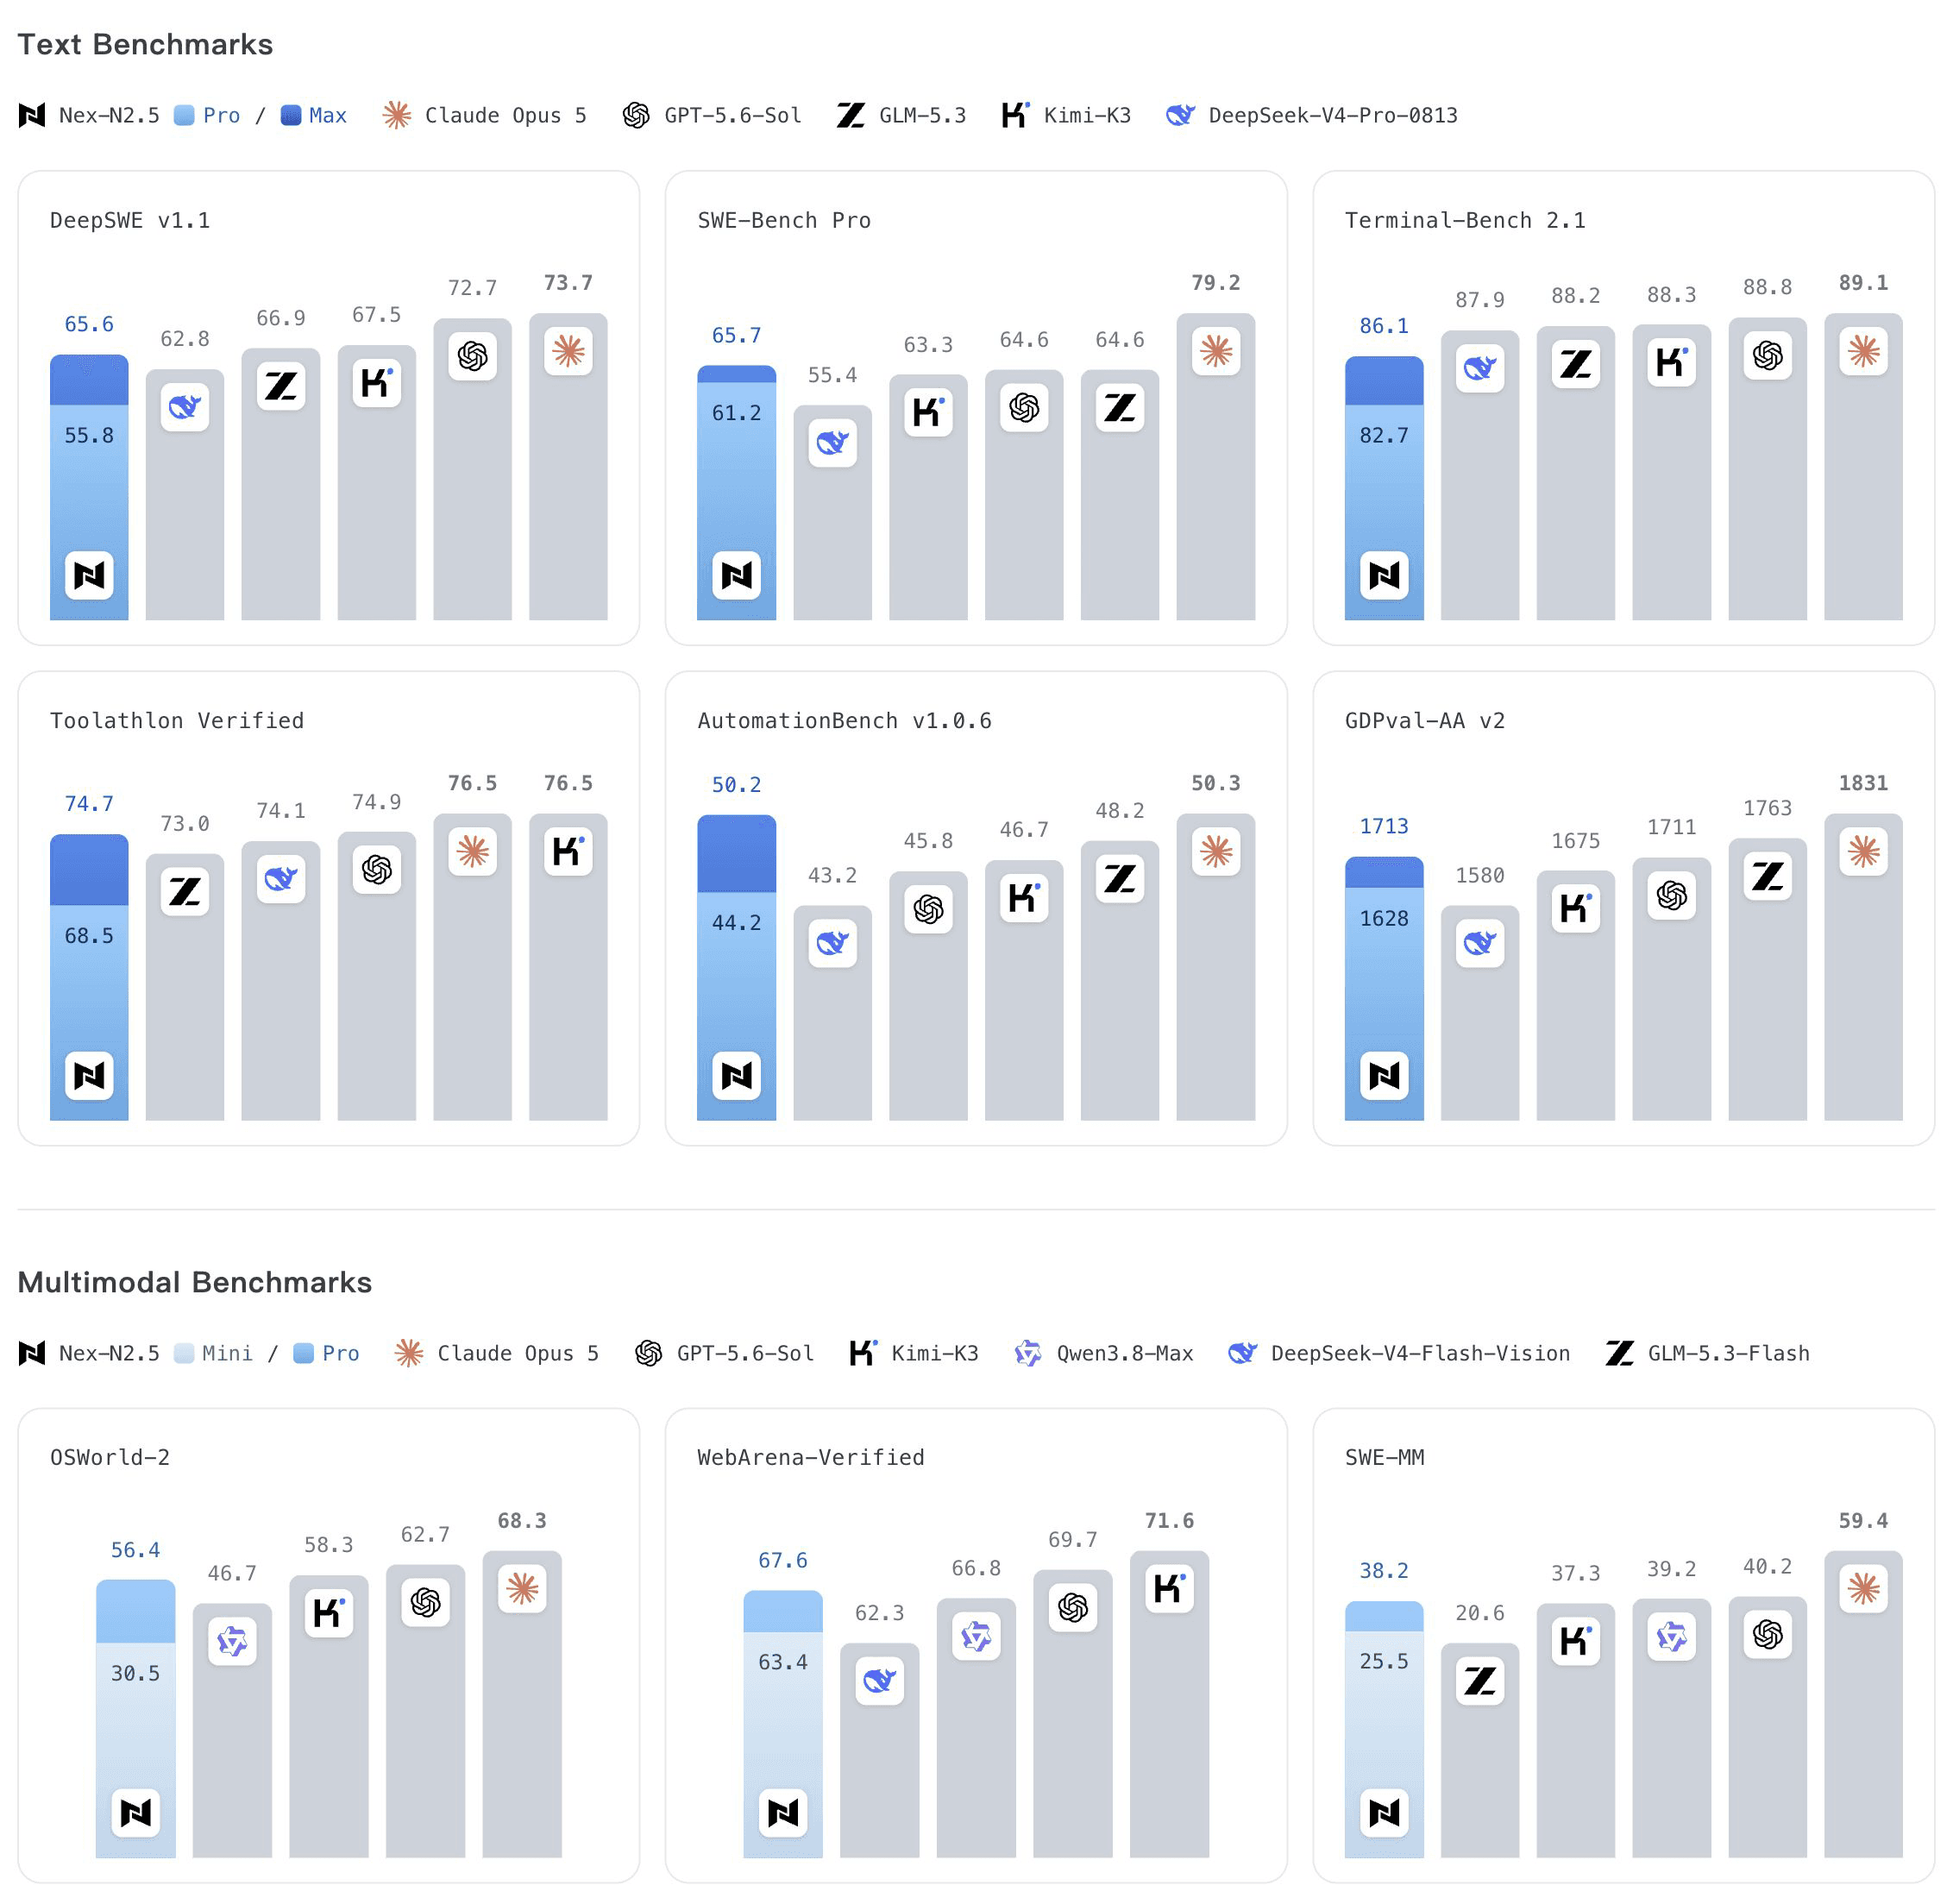
Nex-N2.5-Pro arrives as an Apache-2.0 MoE vision model

A permissively licensed multimodal mixture-of-experts model built on a Qwen3-style MoE backbone.

Sep 8, 2026
Vision-LanguageText / LLM
Nex-N2.5-Pro
Nex Agi/Text / LLMConsumer GPU

Nex AGI releases Nex-N2.5-mini, an open MoE multimodal model

The compact mixture-of-experts model handles both text and vision, and ships under a permissive Apache-2.0 license.

Sep 8, 2026
Text / LLMVision-Language
Nex-N2.5-mini
Monday, September 7, 2026

1 release

Thesysdev/Text / LLMConsumer GPU

OUI-1: A Gemma-based diffusion model for generative UI

Thesys releases an experimental diffusion language model aimed at turning prompts into user interfaces, built atop Google's Gemma.

Sep 7, 2026
Text / LLMCode
OUI-1
Sunday, September 6, 2026

1 release

OpenBMB/Text / LLMRuns anywhere

OpenBMB's MiniCPM5-2B targets on-device AI

The compact 2-billion-parameter model adds long-context handling and tool-calling in a footprint small enough to run locally.

Sep 6, 2026
Text / LLM
MiniCPM5-2B
Saturday, September 5, 2026

2 releases

TokenRhythm/Text / LLMRuns on a laptop

NeoHorse-1-9B targets agentic coding tasks

A 9-billion-parameter model built on Qwen3.5 aims squarely at tool use and code generation.

Sep 5, 2026
Text / LLMCode
NeoHorse-1-9B
TokenRhythm/Text / LLMRuns on a laptop

NeoHorse-1-4B tunes Qwen3.5 for agentic work

A compact 4-billion-parameter model built for tool use, coding, and multi-step reasoning arrives from TokenRhythm.

Sep 5, 2026
Text / LLMCode
NeoHorse-1-9B
Friday, September 4, 2026

2 releases

inclusionAI/Vision-LanguageWorkstation GPU

inclusionAI Adds Vision to Ling 3.0 Flash

The new Ling-3.0-flash-VL brings a mixture-of-experts vision-language model to inclusionAI's open lineup under a permissive MIT license.

Sep 4, 2026
Vision-LanguageText / LLM
Ling-3.0-flash-VL
TaichuAI/Vision-LanguageRuns on a laptop

Taichu 5.0 Brings a 9B Vision-Language Model to Hugging Face

The compact multimodal model targets spatial reasoning, video understanding, and agent-style tasks.

Sep 4, 2026
Vision-Language
ZDTaichu5.0-9B
Thursday, September 3, 2026

4 releases

Unknown/Text / LLMConsumer GPU

Occamy-1.0 targets long-horizon agent work at 35B

A new open 35B model is tuned for multi-step, co-working tasks rather than one-shot answers.

Sep 3, 2026
Text / LLMReasoning
OpenBMB/Embeddings

NeoMME: a single-tower multilingual multimodal encoder

A new open encoder aims to make document retrieval faster by treating text and images natively in one model.

Sep 3, 2026
EmbeddingsVision-Language
NVIDIA/Vision-LanguageRuns anywhere

NVIDIA's Nemotron 3.5 Parse Targets Document OCR

A new vision-language model from NVIDIA is tuned specifically for reading and structuring documents rather than general chat.

Sep 3, 2026
Vision-Language
Nemotron 3.5 Parse
inclusionAI/Text / LLMWorkstation GPU

inclusionAI Tunes Ling-3.0-flash for Finance

A finance-focused variant of the Ling-3.0-flash MoE model targets financial research and agentic tool use.

Sep 3, 2026
Text / LLM
Ling-3.0-flash-Fin
Wednesday, September 2, 2026

3 releases

inclusionAI/Text → ImageRuns on a laptop

LLaDA-Image: A Fully Open 6B Image Generator

inclusionAI pairs a diffusion transformer with a frozen vision-language model and publishes the entire training recipe.

Sep 2, 2026
Text → ImageImage Editing
Microsoft/Speech → TextRuns on a laptop

Microsoft's VibeVoice ASR brings streaming speech-to-text

A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.

Sep 2, 2026
Speech → Text
VibeVoice-ASR-Streaming-7B
Fla Hub/Text / LLMConsumer GPU

RWKV7-G1j arrives as a 13.3B attention-free model

The latest RWKV7 checkpoint scales the recurrent, attention-free architecture to 13.3 billion parameters under a permissive Apache 2.0 license.

Sep 2, 2026
Text / LLM
RWKV7-G1j-13.3B
Tuesday, September 1, 2026

6 releases

IFM/Text / LLMMulti-GPU server

IFM releases K2-Horizon, a 375B open-weight MoE

The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.

Sep 1, 2026
Text / LLMReasoning
K2-Horizon-375B-A23B
IFM/Text / LLMRuns on a laptop

IFM releases K2-Horizon-7B with open pretraining data

The dense 7-billion-parameter model ships as open weights alongside the datasets used to train it.

Sep 1, 2026
Text / LLM
K2-Horizon-375B-A23B
IFM/Text / LLMConsumer GPU

IFM's K2-Horizon MoVA Ships as a 36B MoE Model

The open-weight language model activates just 4B of its 36B parameters per token, aiming for efficiency without shedding capacity.

Sep 1, 2026
Text / LLM
K2-Horizon-MoVA-36B-A4B
NVIDIA/Speech → TextRuns anywhere

NVIDIA's Nemotron-3 Brings Streaming Speaker Diarization

The new open model applies NVIDIA's Sortformer approach to identify who's speaking, in real time.

Sep 1, 2026
Speech → Text
Nemotron-3-Diarization
Jinaai/Vision-LanguageRuns anywhere

Jina AI Releases Jina-OCR-v1 for Document Intelligence

The new vision-language model targets multilingual OCR and structured document understanding on a DeepSeek-VL backbone.

Sep 1, 2026
Vision-Language
jina-ocr-v1
NVIDIA/Any-to-Any

NVIDIA's Kumo Takes Aim at Tabular Prediction

A new foundation model targets structured data, where spreadsheets and databases still dominate real-world machine learning.

Sep 1, 2026
Any-to-Any
Kumo Tabular
Monday, August 31, 2026

2 releases

Viggle/Image → VideoWorkstation GPU

Viggle Releases Viggle-Animate for Character Swaps

The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.

Aug 31, 2026
Image → Video
Viggle-Animate
DeepSeek/Vision-LanguageMulti-GPU server

DeepSeek adds vision to its V4 Flash line

An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.

Aug 31, 2026
Vision-LanguageText / LLM
DeepSeek-V4-Flash-Vision-Exp
Sunday, August 30, 2026

1 release

H company/Embeddings

H Company's NeoMME rethinks visual document retrieval

A single-tower multimodal encoder aims to make multilingual document search cheaper to fine-tune and run.

Aug 30, 2026
EmbeddingsVision-Language
Thursday, August 27, 2026

2 releases

Tencent/Text / LLMDatacenter

Tencent Previews Hunyuan Hy4, an Apache MoE Model

The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.

Aug 27, 2026
Text / LLMReasoning
Hunyuan Hy4 (preview)
Qwen · Alibaba/Vision-LanguageRuns on a laptop

Qwen-Drive 1.0 targets autonomous driving with a 4B VLM

Alibaba's Qwen team brings its vision-language stack to the road with a compact model built for perception and motion planning.

Aug 27, 2026
Vision-Language
Qwen-Drive-1.0-4B
Tuesday, August 25, 2026

4 releases

BreezeBlue/Text → SpeechRuns on a laptop

Breeze-TTS-2 Brings Open Voice Cloning to English

BreezeBlue's second-generation text-to-speech model pairs voice cloning with controllable direction, all under an open release on Hugging Face.

Aug 25, 2026
Text → Speech
Breeze-TTS-2
IBM/Text / LLM

IBM's Granite 4.2 Adds Reasoning to Open LLM Line

The latest update to IBM's Apache 2.0 model family leans into structured reasoning while keeping its enterprise-friendly licensing.

Aug 25, 2026
Text / LLMReasoning
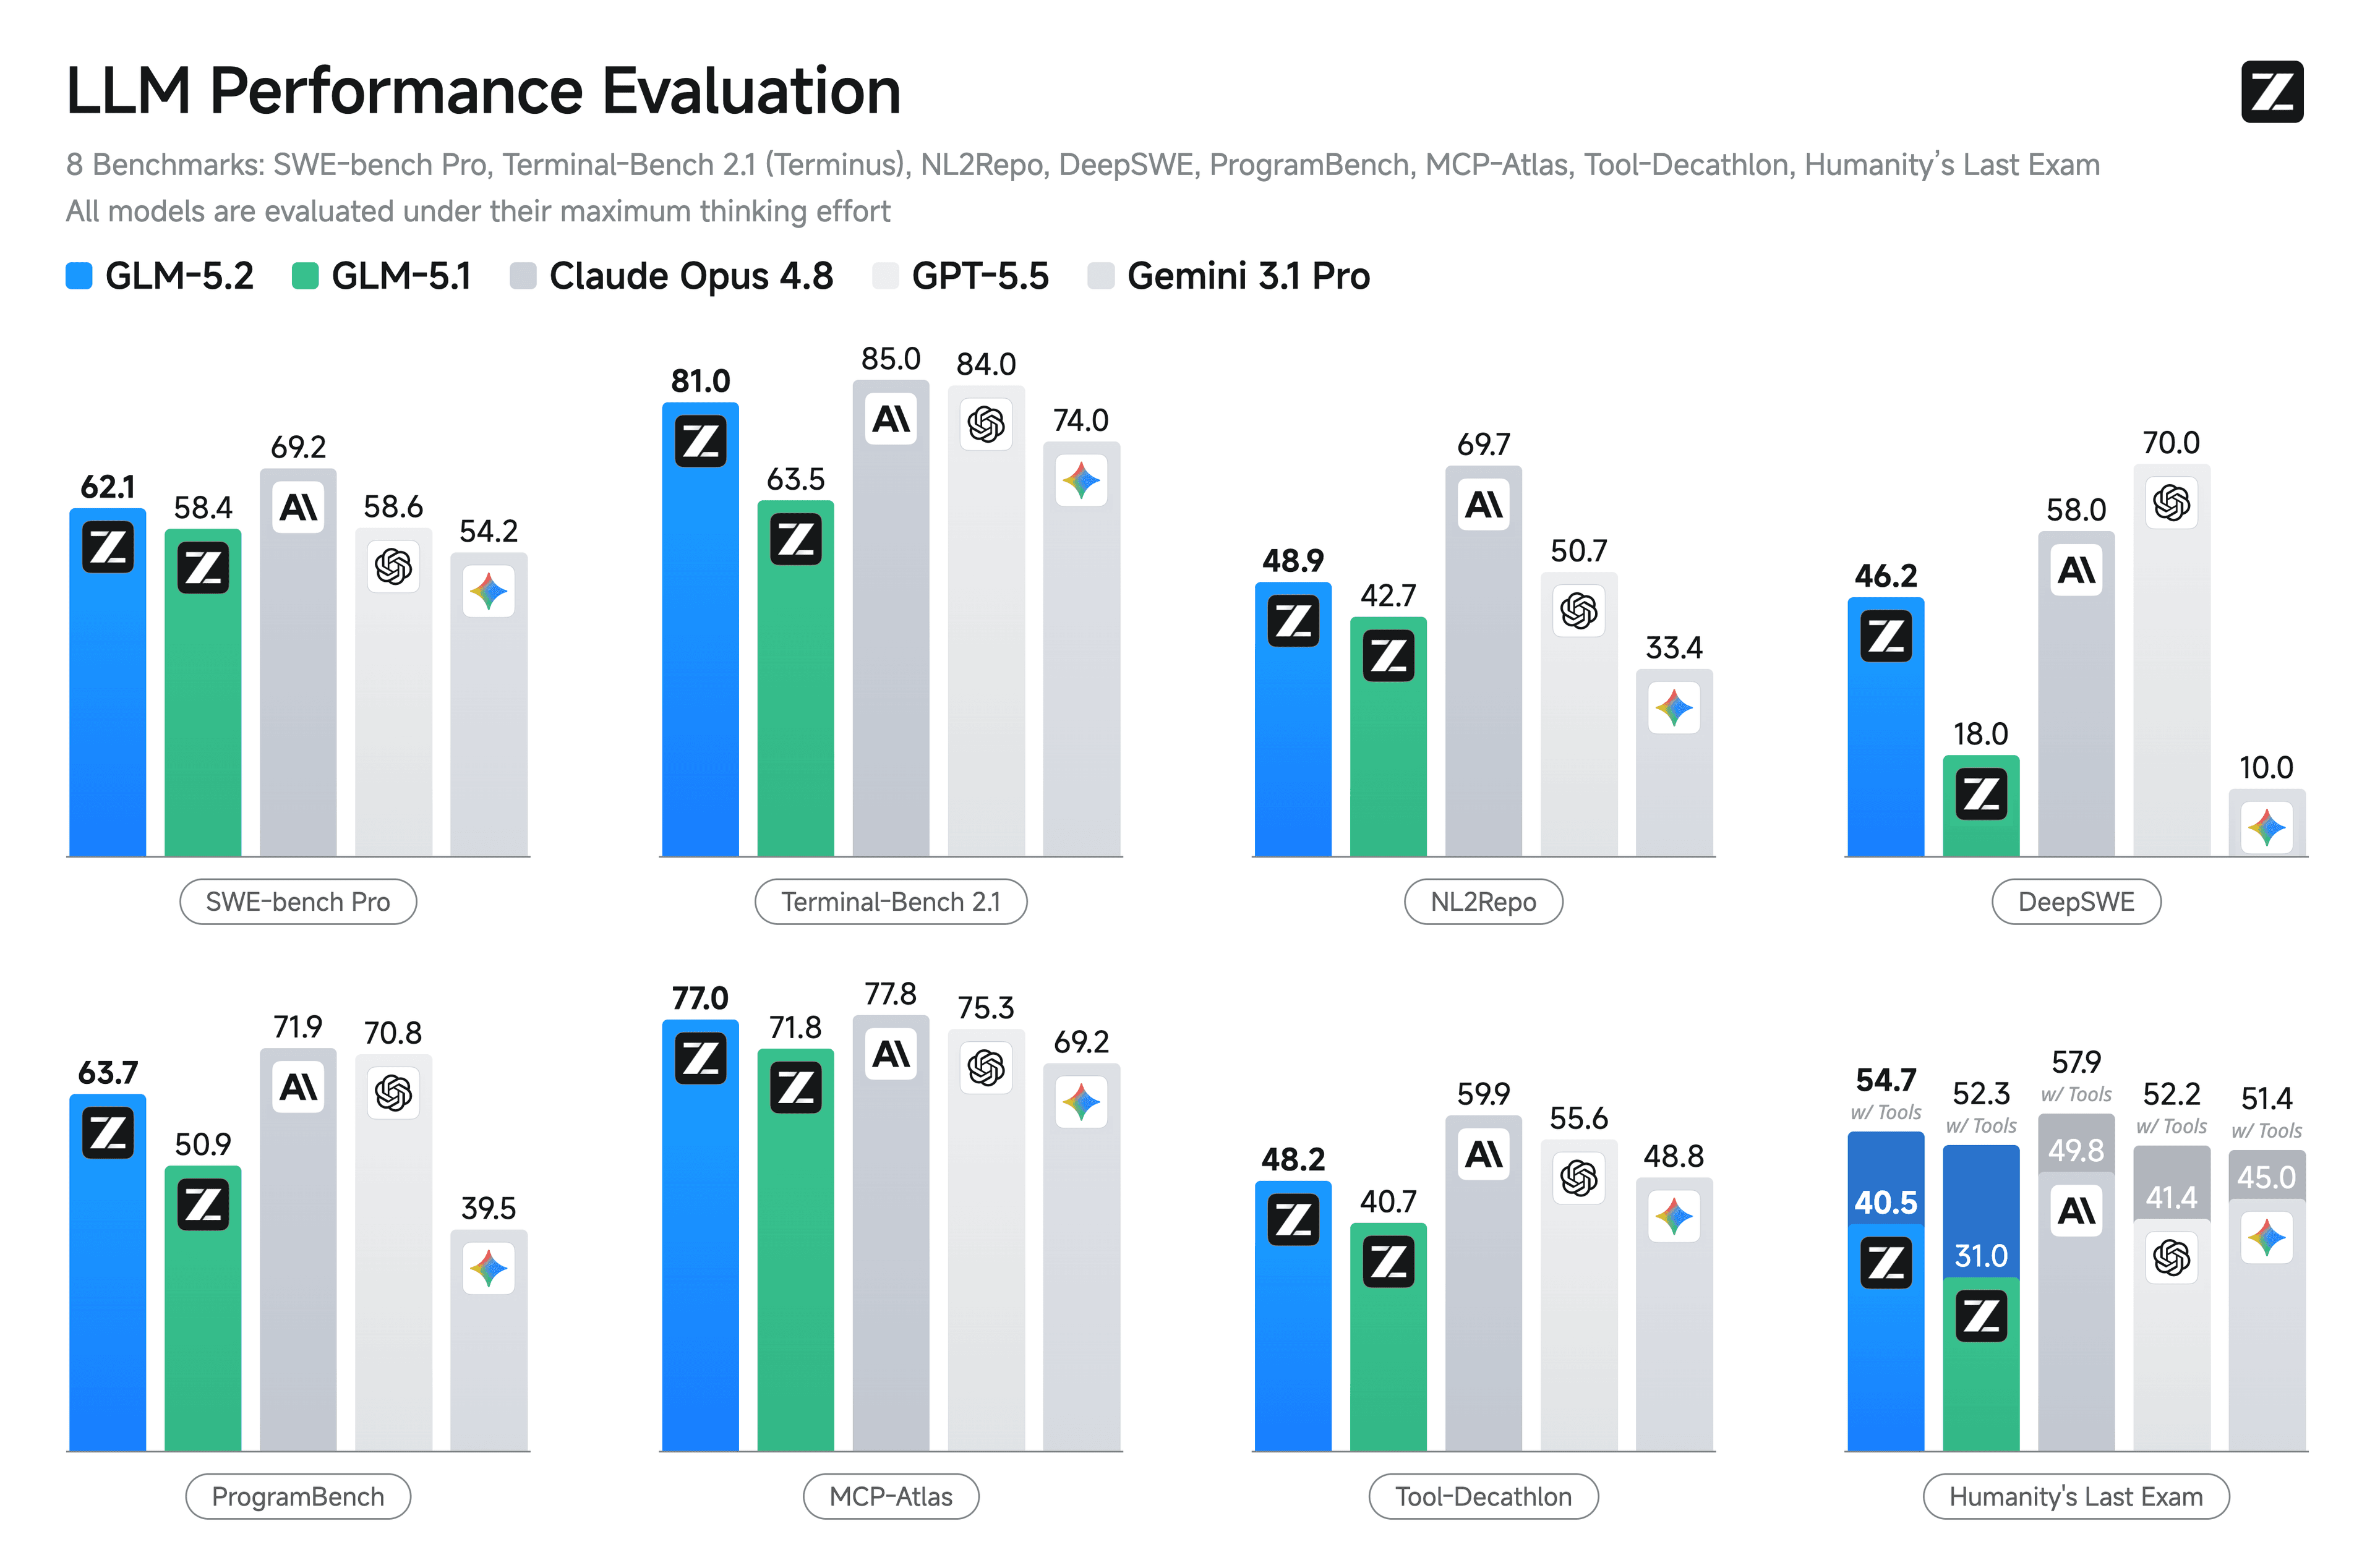
Zhipu AI/Text / LLMMulti-GPU server

Zhipu releases GLM-5.3-Flash under MIT license

A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.

Aug 25, 2026
Text / LLMVision-Language
GLM-5.3-Flash
Tencent/EmbeddingsRuns on a laptop

Tencent's WeMM-Embedding-9B Unifies Text, Image and Video

The WeChat team releases a 9-billion-parameter multimodal embedding model that maps three modalities into one shared vector space.

Aug 25, 2026
EmbeddingsVision-Language
WeMM
Monday, August 24, 2026

2 releases

Pipecat Ai/Text / LLMConsumer GPU

NVIDIA's PhoneLLM Targets Voice Agents on the Line

An early alpha release brings a Nemotron-H mixture-of-experts model tuned for phone-based tool use and function calling.

Aug 24, 2026
Text / LLM
phonellm-alpha-1
XHToken/Text / LLMRuns on a laptop

XHToken releases Spark-X2.5, a 4B open LLM

The Apache-2.0 instruction-tuned model targets developers who want a small, permissively licensed text generator.

Aug 24, 2026
Text / LLM
Spark-X2.5-4B
Sunday, August 23, 2026

1 release

Zhipu AI/Text / LLM

Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost

The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.

Aug 23, 2026
ReasoningText / LLM
Thursday, August 20, 2026

2 releases

NVIDIA/Text / LLM

Liquid AI's LFM2.5-DSpark targets faster inference

The new efficient language model claims up to 3.2x faster inference, extending Liquid AI's push toward lean, deployable models.

Aug 20, 2026
Text / LLM
Unknown/Text / LLM

Liquid AI's LFM2.5-DSpark targets faster inference

The company's latest LFM2.5 variant promises up to 3.2x faster inference without leaning on cloud-scale hardware.

Aug 20, 2026
Text / LLM
Wednesday, August 19, 2026

2 releases

SenseTime/Any-to-AnyRuns on a laptop

SenseTime Releases SenseNova U1.5 8B Any-to-Any Model

The new 8B multimodal model handles text, images, and image editing within a single native architecture.

Aug 19, 2026
Any-to-Any
SenseNova-U1.5-8B-MoT
Audio8/Text → SpeechRuns anywhere

Audio8 debuts a compact 0.1B preview TTS model

The lightweight text-to-speech model brings zero-shot voice cloning to a footprint small enough to run almost anywhere.

Aug 19, 2026
Text → Speech
Audio8-TTS-Preview-0.1b
Tuesday, August 18, 2026

4 releases

Thomsonreuters/Text / LLMConsumer GPU

Thomson Reuters enters the model race with Thomson-1.0

The information giant's first frontier model is a mixture-of-experts system tuned on its proprietary legal, tax, and news data.

Aug 18, 2026
Text / LLMVision-Language
Thomson-1.0-Small
Tencent/Text → Speech

Tencent's AuK Bundles Voice Cloning and Speech Editing

The new open-weights model handles zero-shot TTS alongside enhancement and separation, aiming to be a broad speech toolkit rather than a single-purpose voice engine.

Aug 18, 2026
Text → Speech
AuK
Ornith Ai/Text / LLMMulti-GPU server

Ornith 1.5 arrives as a 397B MoE multimodal model

The MIT-licensed release spans a 397B mixture-of-experts flagship plus 9B and 35B-A3B variants for lighter deployments.

Aug 18, 2026
Vision-LanguageText / LLM
Ornith-1.5-122B
Ornith Ai/Text / LLMConsumer GPU

Ornith 1.5 Brings a Lean 35B MoE to Open Weights

The MIT-licensed model activates just 3B parameters per token, borrowing the Qwen3.5 MoE design for text and reasoning tasks.

Aug 18, 2026
Text / LLMReasoning
Ornith-1.5-122B
Monday, August 17, 2026

2 releases

AntResearch/Image → Video

Ant Research releases 4DAnyone for 4D human video

The new open model turns a single input into multiview video and reconstructs humans for novel-view synthesis.

Aug 17, 2026
Image → Video
4DAnyone
Apodex/Text / LLMConsumer GPU

Apodex 1.1 mini targets long-horizon agentic work

An MoE model built on Qwen3.5-35B-A3B aims at complex, multi-step tasks rather than one-shot answers.

Aug 17, 2026
Text / LLMReasoning
Apodex 1.1 mini
Friday, August 14, 2026

5 releases

OpenMOSS/Vision-Language

OpenMOSS Debuts MOSS-VL for Real-Time Vision Interaction

A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.

Aug 14, 2026
Vision-LanguageText / LLM
Fastino/Text / LLMRuns anywhere

Fastino releases GLiNER 2.5 Multi for extraction

A multilingual model built for structured extraction tasks like named-entity recognition, relation extraction, and JSON output.

Aug 14, 2026
Text / LLM
GLiNER 2.5 Multi
StarDoc AI/Vision-LanguageRuns anywhere

StarDoc-AI Releases TeleOCR for Document Parsing

A vision-language model built on Qwen2.5-VL targets bilingual Chinese and English text extraction from documents.

Aug 14, 2026
Vision-Language
TeleOCR
XingChen AGI/Vision-LanguageRuns anywhere

TeleOCR brings bilingual document parsing to Qwen2.5-VL

A new vision-language model targets Chinese and English OCR and structured document extraction, released openly on Hugging Face.

Aug 14, 2026
Vision-Language
TeleOCR
Tencent/Vision-LanguageConsumer GPU

Tencent's UI-Mate-27B targets desktop automation

A 27B vision-language model built to see and operate graphical interfaces, tested on OSWorld and WindowsAgentArena.

Aug 14, 2026
Vision-Language
UI-Mate-27B
Thursday, August 13, 2026

2 releases

DeepSeek/Text / LLMDatacenter

DeepSeek Releases V4-Pro-0813 With Open Weights

The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.

Aug 13, 2026
Text / LLMReasoning
DeepSeek-V4-Pro-0813
DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model

The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.

Aug 13, 2026
Text / LLMReasoning
DeepSeek-V4-Pro-0813
Wednesday, August 12, 2026

2 releases

Superwhisper/Speech → TextRuns anywhere

Superwhisper's s1-mini polishes raw speech-to-text output

A compact Qwen3-based model tackles the unglamorous cleanup work that makes transcripts readable.

Aug 12, 2026
Speech → Text
s1-mini
LiquidAI/Vision-LanguageRuns anywhere

Liquid AI's LFM2.5-VL-3B targets on-device vision

The 3-billion-parameter vision-language model is tuned for faster multimodal work on edge hardware.

Aug 12, 2026
Vision-Language
LFM2.5-VL-3B
Monday, August 10, 2026

8 releases

NVIDIA/Text → Speech

NVIDIA Opens Magpie TTS for Multilingual Voice Agents

The open-weights text-to-speech model targets low-latency, deployable voice agents across multiple languages.

Aug 10, 2026
Text → Speech
NVIDIA/Text → Speech

NVIDIA Opens Magpie TTS for Multilingual Voice Agents

The open-weights text-to-speech model targets low-latency speech synthesis with full control over deployment.

Aug 10, 2026
Text → Speech
NVIDIA/Text → Speech

NVIDIA opens Magpie TTS for multilingual voice agents

The company releases open weights for a low-latency, multilingual text-to-speech model aimed at real-time conversational systems.

Aug 10, 2026
Text → Speech
Cohere/Vision-LanguageRuns anywhere

Cohere Labs releases compact North Micro Vision model

A small multilingual vision-language model built for instruction following arrives under a research-only license.

Aug 10, 2026
Vision-Language
North Micro Vision Instruct
Shunyalabs/Speech → Text

Vak Conformer targets speech recognition in six Indic languages

Shunya Labs releases a Conformer-based ASR model aimed at India's underserved language landscape.

Aug 10, 2026
Speech → Text
Vak Conformer
IndexTeam/Text → Speech

Bilibili's IndexTTS-2.5 Refines Zero-Shot Voice Cloning

The latest text-to-speech model from bilibili's Index team pairs voice cloning with emotion control across Chinese, English, and Japanese.

Aug 10, 2026
Text → Speech
IndexTTS-2.5
inclusionAI/Text / LLMRuns on a laptop

inclusionAI Releases Ling-3.0-tiny, an MIT-Licensed MoE

The new hybrid mixture-of-experts model targets efficient text generation under a permissive license.

Aug 10, 2026
Text / LLM
Ling-3.0-tiny
Meta AI/Vision-LanguageMajor releaseConsumer GPU

Meta's Muse Glimmer 30B Targets Local Agentic Coding

A 30-billion-parameter multimodal model built to run locally, released under Apache 2.0 with an eye on agentic coding workflows.

Aug 10, 2026
Vision-LanguageCode
Muse Glimmer 30B
Sunday, August 9, 2026

1 release

Dots Studio/Any-to-AnyMulti-GPU server

dots3-note preview brings audio and vision to one model

An early build of a multimodal, long-context agentic system arrives on Hugging Face with support for both images and sound.

Aug 9, 2026
Any-to-AnyVision-Language
dots3-note (preview)
Saturday, August 8, 2026

1 release

Qwen · Alibaba/Text / LLMMajor releaseDatacenter

Qwen releases 2.4T-parameter open MoE with 95B active

Alibaba's Qwen team pushes its largest sparse model yet, activating 95 billion parameters per token from a 2.4-trillion-parameter pool.

Aug 8, 2026
Text / LLMReasoning
Qwen3.8-2.4T-A95B
Friday, August 7, 2026

3 releases

IBM/Text / LLMConsumer GPU

IBM's Granite 4.2 30B adds reasoning and tool calls

The new dense model brings optional step-by-step thinking and function calling under a permissive Apache-2.0 license.

Aug 7, 2026
Text / LLMReasoning
Granite 4.2 30B
MiniMax/MusicRuns anywhere

MiniMax Opens Its Music3 Text-to-Music Model

The Chinese AI lab brings its music generation system to Hugging Face, expanding the roster of open audio models.

Aug 7, 2026
Music
MiniMax-Music3
Motif Technologies/Text / LLMMulti-GPU server

Motif 3 brings a sparse MoE approach to reasoning

Motif Technologies debuts a mixture-of-experts language model built around grouped differential latent attention for long-context reasoning and code.

Aug 7, 2026
Text / LLMReasoning
Motif 3
Wednesday, August 5, 2026

2 releases

OpenMOSS/Text / LLMRuns on a laptop

MameLoshnLM Brings Yiddish Into the Open LLM Era

OpenMOSS releases what it calls the first open-source 8B language model built specifically for Yiddish, paired with an evaluation benchmark.

Aug 5, 2026
Text / LLM
Qwen · Alibaba/Vision-LanguageMajor releaseConsumer GPU

Qwen3.8-27B Brings Vision to a Dense Model

Alibaba's latest Qwen release pairs image understanding with text under a permissive Apache-2.0 license.

Aug 5, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Tuesday, August 4, 2026

3 releases

Deepgrove/ReasoningRuns on a laptop

Deepgrove's Maple Preview bets on ternary-weight MoE

A permissively licensed reasoning model that pairs a mixture-of-experts design with ternary weights, aiming for efficiency.

Aug 4, 2026
ReasoningText / LLM
Maple Preview
NVIDIA/Text / LLMRuns on a laptop

NVIDIA's Nemotron 3.5 Lightning trims MoE for speed

A 30-billion-parameter mixture-of-experts model activates just 3 billion parameters per token, using a hybrid Mamba design to keep inference fast.

Aug 4, 2026
Text / LLMReasoning
Nemotron-3.5-Lightning-30B-A3B
Mistral AI/Vision-LanguageRuns anywhere

Mistral debuts Shieldstral, a 3B safety model

The open-weights multimodal moderation model brings content safety checks to both text and images under an Apache 2.0 license.

Aug 4, 2026
Vision-LanguageAny-to-Any
Sunday, August 2, 2026

1 release

inclusionAI/Text / LLMWorkstation GPU

inclusionAI ships Ling-3.0-flash, an MIT-licensed MoE model

The latest entry in the Bailing family pairs a hybrid mixture-of-experts design with a permissive license aimed at fast, low-cost text generation.

Aug 2, 2026
Text / LLM
Ling-3.1-flash
Saturday, August 1, 2026

2 releases

LiquidAI/EmbeddingsRuns anywhere

Liquid AI ships LFM2.5, a 2.6B on-device model

The latest Liquid Foundation Model targets multilingual text generation on laptops and phones, packaged in GGUF for local runtimes.

Aug 1, 2026
Text / LLM
LFM2.5-24B-A2B
NVIDIA/Text / LLMConsumer GPU

NVIDIA's Nemotron 3.5 Lightning Blends Mamba and MoE

A 30B mixture-of-experts model with just 3B active parameters aims at fast, agentic coding workloads.

Aug 1, 2026
Text / LLMReasoning
Nemotron-3.5-Lightning-30B-A3B
Friday, July 31, 2026

4 releases

Meituan/Text / LLMWorkstation GPU

Meituan Ships a Lighter, Sparser LongCat-Flash

The food-delivery giant's newest open model trims its mixture-of-experts design for more efficient inference under an MIT license.

Jul 31, 2026
Text / LLM
LongCat-Flash-Lite-Sparse
DeepSeek/Text / LLMMulti-GPU server

DeepSeek Ships V4-Flash, a 304B MoE Tuned for Agents

The latest checkpoint in DeepSeek's V4 line leans into agentic workflows while keeping the permissive MIT license.

Jul 31, 2026
Text / LLMReasoning
DeepSeek-V4-Flash-0731
DeepSeek/Text / LLMMajor releaseMulti-GPU server

DeepSeek Refreshes V4-Flash With New 0731 Checkpoint

The MIT-licensed mixture-of-experts model returns in an updated build shipping with FP8 weights for cheaper inference.

Jul 31, 2026
Text / LLMReasoning
DeepSeek-V4-Flash-0731
Lodestones/Text → Image

Kroma: An MIT-Licensed Text-to-Image Model for ComfyUI

Lodestones releases an open image generator built on the Krea 2 lineage, aimed squarely at ComfyUI workflows.

Jul 31, 2026
Text → Image
Kroma
Wednesday, July 29, 2026

3 releases

NVIDIA/Text → SpeechRuns on a laptop

NVIDIA's Nemotron VoiceChat 11B Targets Spoken AI

An 11-billion-parameter voice conversation model built atop Nemotron Nano 9B v2 arrives on Hugging Face.

Jul 29, 2026
Text → SpeechAny-to-Any
Nemotron VoiceChat 11B
Cactus Compute/Text / LLM

Needle2 Packs an Agentic LLM Into 14MB

Cactus Compute's tiny model brings tool and function calling to phones, wearables, and robots.

Jul 29, 2026
Text / LLMCode
Needle2
LGAI EXAONE/Text / LLMDatacenter

LG AI Research debuts K-EXAONE 2.0, a 750B MoE model

The new mixture-of-experts model activates 37B parameters per token and targets English, Korean, and Spanish reasoning tasks.

Jul 29, 2026
Text / LLMReasoning
K-EXAONE 2.0 750B-A37B
Tuesday, July 28, 2026

5 releases

LiquidAI/EmbeddingsRuns anywhere

Liquid AI's LFM2.5-2.6B targets on-device agents

A compact 2.6-billion-parameter model built to run local, multilingual agents without leaning on the cloud.

Jul 28, 2026
Text / LLM
LFM2.5-24B-A2B
MiniMax/Text → VideoWorkstation GPU

MiniMax Releases H3 Video Model on Hugging Face

The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.

Jul 28, 2026
Text → VideoImage → Video
MiniMax-H3
Skt/Text / LLMDatacenter

SK Telecom Releases A.X-K2 Multilingual LLM

The Korean telecom carrier's latest open language model targets English, Korean, Chinese, Japanese, and Spanish under a permissive license.

Jul 28, 2026
Text / LLM
A.X-K2
SenseTime/Any-to-AnyRuns on a laptop

SenseTime Debuts SenseNova U1.5 8B Multimodal Preview

An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.

Jul 28, 2026
Any-to-AnyVision-Language
SenseNova-U1.5-8B-MoT
Audio8/Text → SpeechRuns anywhere

Audio8 debuts a 0.6B multilingual zero-shot TTS preview

The compact text-to-speech model promises voice cloning across languages from a footprint small enough to run without heavy hardware.

Jul 28, 2026
Text → Speech
Audio8-TTS-Preview-0.1b
Monday, July 27, 2026

4 releases

Thinkingmachines/Vision-LanguageMulti-GPU server

Thinking Machines Debuts Inkling Small, a Compact Multimodal MoE

The Apache-2.0 model brings mixture-of-experts efficiency to image, audio, and text tasks in a smaller footprint.

Jul 27, 2026
Vision-LanguageText / LLM
Inkling Small
LiquidAI/EmbeddingsRuns anywhere

Liquid AI's LFM2.5 encoder targets fast CPU inference

A 230M-parameter bidirectional encoder built for long-context English and German embeddings without a GPU.

Jul 27, 2026
Embeddings
LFM2.5-Encoder-230M
LiquidAI/EmbeddingsRuns anywhere

Liquid AI ships a 350M encoder built for CPUs

The compact LFM2.5 encoder targets fast, long-context text embeddings without a GPU.

Jul 27, 2026
Embeddings
LFM2.5-Encoder-350M
KRAFTON/Any-to-AnyRuns on a laptop

KRAFTON releases A.X-K2 Raon speech MoE model

The game maker's new open model blends text-to-speech and speech recognition in a single 21B mixture-of-experts system with just 3B active parameters.

Jul 27, 2026
Any-to-AnyText → Speech
A.X-K2 Raon Speech 21B-A3B
Sunday, July 26, 2026

1 release

Microsoft/Vision-LanguageRuns on a laptop

Microsoft's Mage-VL Streams Video Natively

A codec-native multimodal foundation model aims to understand live video and vision-language input in real time.

Jul 26, 2026
Vision-LanguageAny-to-Any
Mage-VL
Friday, July 24, 2026

2 releases

Swiss Ai/Text / LLMWorkstation GPU

Apertus v1.5 70B arrives with an Apache-2.0 license

Switzerland's open-model effort ships a 70-billion-parameter, multilingual and multimodal system that anyone can use, modify, and deploy.

Jul 24, 2026
Text / LLMVision-Language
Apertus v1.5 70B
Microsoft/Speech → TextRuns anywhere

Microsoft's VibeVoice ASR Goes BitNet for CPU Speech

A BitNet-quantized speech recognition model trades GPU dependence for efficient CPU inference in English and Chinese.

Jul 24, 2026
Speech → Text
VibeVoice ASR BitNet
Thursday, July 23, 2026

3 releases

Amd/ReasoningRuns on a laptop

AMD's Instella-MoE Brings Reasoning to ROCm Hardware

A new open mixture-of-experts model with 16B total parameters and just 3B active is tuned to run on AMD's own accelerator stack.

Jul 23, 2026
ReasoningText / LLM
Instella-MoE 16B A3B Think
Kwaipilot/CodeConsumer GPU

Kwaipilot Releases KAT-Coder V2.5 Dev, an Agentic MoE Coder

Kuaishou's coding team ships an open mixture-of-experts model built on the Qwen3.5 MoE architecture and tuned for agentic development work.

Jul 23, 2026
CodeText / LLM
KAT-Coder V2.5 Dev
Lightricks/Image → Video

Lightricks Releases LTX-2.5 Video Model

The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.

Jul 23, 2026
Text → VideoImage → Video
LTX-2.5
Wednesday, July 22, 2026

1 release

Upstage/Text / LLMMulti-GPU server

Upstage's Solar Open2 arrives as a 250B MoE model

The Korean AI firm's latest open release scales to 250 billion parameters with a mixture-of-experts design tuned for English and Korean.

Jul 22, 2026
Text / LLM
Solar Open2 250B
Tuesday, July 21, 2026

2 releases

Microsoft/Text → ImageRuns on a laptop

Microsoft's Mage-Flow packs image editing into 4B

A compact model handles both text-to-image generation and instruction-based edits at native resolution, under a permissive MIT license.

Jul 21, 2026
Text → ImageImage Editing
Mage-Flow
Nanbeige/Text / LLMRuns on a laptop

Nanbeige 4.2 arrives as a compact 3B bilingual model

The new English-Chinese language model targets efficient deployment in a small parameter footprint.

Jul 21, 2026
Text / LLM
Nanbeige4.3-33B
Monday, July 20, 2026

1 release

Motif Technologies/Text / LLMMulti-GPU server

Motif Technologies debuts Motif 3 Beta, an MoE model

The Korean AI lab's preview release is a mixture-of-experts language model built for long-context, multilingual work.

Jul 20, 2026
Text / LLM
Motif 3
Friday, July 17, 2026

1 release

Microsoft/Vision-LanguageConsumer GPU

Microsoft's Fara1.5-27B targets computer-use agents

A 27B-parameter vision-language model built to drive browsers and desktop apps like a human operator.

Jul 17, 2026
Vision-Language
Fara1.5-27B
Thursday, July 16, 2026

6 releases

NVIDIA/Any-to-Any

NVIDIA's Audio-Visual Flamingo Fuses Sound and Sight

A fully open multimodal model aims to reason jointly across audio, images, and long-form video.

Jul 16, 2026
Any-to-AnyVision-Language
Unknown/Text / LLMConsumer GPU

German consortium releases open 30B model Soofi S

A collaborative European effort ships a dense 30-billion-parameter model that claims top marks on both English and German benchmarks.

Jul 16, 2026
Text / LLM
NVIDIA/EmbeddingsRuns on a laptop

NVIDIA's Nemotron-3-Embed 8B tops RTEB retrieval test

The 8-billion-parameter text embedding model claims the number one overall spot on the RTEB benchmark, with an eye toward agentic retrieval.

Jul 16, 2026
Embeddings
Nemotron-3-Embed 8B
Internlm/Vision-LanguageMulti-GPU server

InternLM Previews 397B Vision-Language Model

The Intern-S2 preview arrives as a very large multimodal system under a permissive Apache-2.0 license.

Jul 16, 2026
Vision-Language
Intern-S2-Preview-397B
Mistral AI/Vision-LanguageRuns on a laptop

Mistral's Shieldstral brings safety checks to images

A compact 3B open-weights classifier flags unsafe text and visual content, and ships under Apache 2.0.

Jul 16, 2026
Vision-LanguageText / LLM
Shieldstral 1.0 3B
inclusionAI/Text / LLMWorkstation GPU

inclusionAI ships LLaDA2.2-flash diffusion LLM

A new Apache-2.0 mixture-of-experts model that generates text through diffusion rather than left-to-right decoding.

Jul 16, 2026
Text / LLM
LLaDA2.2-flash
Wednesday, July 15, 2026

3 releases

OpenAI/Any-to-Any

Thinking Machines ships Inkling, its first open model

The Mira Murati-founded lab makes its debut with an open-weights, reasoning-focused language model.

Jul 15, 2026
Text / LLMReasoning
Thinkingmachines/Any-to-AnyMajor releaseDatacenter

Thinking Machines Lab debuts Inkling, its first open model

The lab's inaugural open-weights release is a mixture-of-experts system that takes image and audio inputs, shipped under a permissive Apache 2.0 license.

Jul 15, 2026
Any-to-AnyVision-Language
Inkling
Nyralabs/Speech → TextRuns anywhere

CrisperWhisper 2.0 Large targets verbatim transcription

A Whisper-based ASR model that keeps every filler word and stamps timestamps to the individual word, now covering English and German.

Jul 15, 2026
Speech → Text
CrisperWhisper 2.0 Large
Tuesday, July 14, 2026

4 releases

Qwen · Alibaba/Image → VideoRuns on a laptop

Alibaba's Wan2.2-Animate-2 14B lands under Apache 2.0

A permissively licensed 14B video model aimed at character animation joins the growing Wan family.

Jul 14, 2026
Image → VideoText → Video
Wan2.2-Animate-2 14B
NVIDIA/EmbeddingsRuns anywhere

NVIDIA's Nemotron 3 Embed tops the RTEB leaderboard

A compact 1B-parameter text embedding model claims the top overall spot on a retrieval benchmark aimed at reflecting real-world use.

Jul 14, 2026
Embeddings
Nemotron-3-Embed 8B
OpenMOSS/Vision-LanguageRuns on a laptop

OpenMOSS Debuts MOSS-VL-Realtime for Live Video

The Chinese research group's new vision-language model targets streaming understanding of video and images rather than static frames.

Jul 14, 2026
Vision-LanguageAny-to-Any
MOSS-VL-Realtime
Ai Sage/Speech → Text

SberDevices releases GigaAM Multilingual ASR model

An MIT-licensed speech recognition model targeting Russian, English, and Kazakh arrives on Hugging Face.

Jul 14, 2026
Speech → Text
GigaAM Multilingual
Monday, July 13, 2026

4 releases

inclusionAI/Reasoning

inclusionAI's Ring-Zero Scales Zero-RL to a Trillion Parameters

A new mixture-of-experts model learns to reason through reinforcement learning alone, without human-annotated chains of thought.

Jul 13, 2026
ReasoningText / LLM
Unknown/Any-to-Any

Boogu-Image-0.1 Brings Unified Multimodal to Open Source

A new Apache-licensed model family folds bilingual text-to-image generation and instruction editing into one system.

Jul 13, 2026
Any-to-AnyText → Image
Poolside/CodeWorkstation GPU

Poolside releases Laguna-S-2.1 coding model

The AI coding startup puts a version of its Laguna family on Hugging Face under the permissive OpenMDW license.

Jul 13, 2026
CodeText / LLM
Laguna-S-2.1
ATH MaaS/Vision-LanguageRuns anywhere

Alibaba's OvisOCR2 turns page images into Markdown

A compact 0.8B vision-language model aims to parse full documents—text, tables, and formulas—in a single pass.

Jul 13, 2026
Vision-Language
OvisOCR2
Sunday, July 12, 2026

1 release

Qwen · Alibaba/Music

Qwen Enters Music Generation With Qwen-Music

Alibaba's Qwen team debuts a text-to-song model that produces high-fidelity tracks complete with vocals.

Jul 12, 2026
Music
Friday, July 10, 2026

1 release

Qwen · Alibaba/Image → Video

Wan-Dancer-14B turns still images into dance videos

Alibaba's Wan team releases an Apache-2.0 image-to-video model built for music-driven dance generation.

Jul 10, 2026
Image → Video
Wan-Dancer-14B
Wednesday, July 8, 2026

1 release

robbyant/Text → VideoConsumer GPU

LingBot-Video puts a 30B MoE behind embodied AI video

A DiT-based mixture-of-experts model activates just 3B parameters per step and ships under an Apache 2.0 license.

Jul 8, 2026
Text → Video
LingBot-Video 30B-A3B
Monday, July 6, 2026

1 release

NVIDIA/Any-to-AnyConsumer GPU

NVIDIA's Audex Unifies Audio Understanding and Speech

A new 30B mixture-of-experts model from NVIDIA handles both listening and speaking within a single audio-text architecture.

Jul 6, 2026
Any-to-AnyText → Speech
Nemotron-Labs-Audex-30B-A3B
Sunday, July 5, 2026

1 release

Ai Sage/Text / LLMMulti-GPU server

GigaChat 3.5 arrives as a 432B mixture-of-experts model

The multilingual instruct model activates 28B parameters per token and leans on hybrid attention for efficiency at scale.

Jul 5, 2026
Text / LLM
GigaChat3.5-432B-A28B
Saturday, July 4, 2026

1 release

Prism Ml/Text / LLMConsumer GPU

Bonsai-27B Brings 1-Bit Quantization to Local Inference

A ternary-weight 27B model with hybrid attention aims to run large-model reasoning on everyday hardware.

Jul 4, 2026
Text / LLM
Bonsai-27B
Thursday, July 2, 2026

1 release

Tencent/Text / LLMMulti-GPU server

Tencent releases Hunyuan Hy3 under Apache 2.0

The company's latest mixture-of-experts model arrives as an openly licensed conversational LLM on Hugging Face.

Jul 2, 2026
Text / LLM
Hunyuan Hy3
Wednesday, July 1, 2026

9 releases

NVIDIA/Text → VideoRuns on a laptop

NVIDIA's Cosmos 3 Edge Brings World Models Closer

A new edge-optimized variant of NVIDIA's Cosmos world-model line aims to run generative video where the compute lives.

Jul 1, 2026
Text → VideoImage → Video
Cosmos 3 Edge
NVIDIA/Text → ImageConsumer GPU

NVIDIA distills Qwen-Image for few-step generation

A DMD2-distilled build of Qwen-Image trades sampling steps for speed while keeping the original model's output profile.

Jul 1, 2026
Text → Image
Qwen-Image-Flash
Google DeepMind/Any-to-AnyMajor release

Google DeepMind's Gemma 4 Goes Multimodal and MoE

The new open-weights family adds a mixture-of-experts design, encoder-free multimodal inputs, and an optional thinking mode.

Jul 1, 2026
Any-to-AnyText / LLM
Mistral AI/Text / LLMWorkstation GPU

Mistral's Leanstral 1.5 puts 119B in a lean MoE

The new Apache-2.0 mixture-of-experts model activates just 6B parameters per token, trading raw density for cheaper inference.

Jul 1, 2026
Text / LLMReasoning
Leanstral-1.5-119B-A6B
Soofi Project/Text / LLMConsumer GPU

German Consortium Debuts Soofi S, an Open 30B MoE Model

A Mamba-2 mixture-of-experts model claims top marks in both English and German benchmarks.

Jul 1, 2026
Text / LLM
Soofi S Base
NVIDIA/Text / LLMRuns anywhere

Liquid AI's LFM2.5-230M targets phones and robots

A 230-million-parameter language model built to run on hardware as modest as a Raspberry Pi.

Jul 1, 2026
Text / LLM
Mistral AI/Text / LLMRuns anywhere

Liquid AI's LFM2.5-230M targets phones and robots

A 230-million-parameter model built to run on constrained hardware like Raspberry Pi and edge robotics.

Jul 1, 2026
Text / LLM
IBM/Text / LLMRuns anywhere

Liquid AI's LFM2.5 230M targets phones and robots

A 230-million-parameter language model built to run locally on constrained hardware like the Raspberry Pi.

Jul 1, 2026
Text / LLM
Open Gigaai/Image → Video

GigaAI Releases Giga-World-1 Under Apache 2.0

An open image-to-video world model aims to bridge physically grounded generation and robot policy learning.

Jul 1, 2026
Image → Video
Giga-World-1
Tuesday, June 30, 2026

4 releases

NVIDIA/Vision-LanguageRuns anywhere

NVIDIA's Nemotron-Parse 2.0 targets document OCR

A compact vision-language model built to turn scanned pages and complex layouts into structured, machine-readable text.

Jun 30, 2026
Vision-Language
Nemotron-Parse-2.0
Microsoft/Vision-LanguageRuns on a laptop

Microsoft previews GELab-Zero-4B, a compact GUI agent

The 4-billion-parameter vision-language model targets on-screen and mobile automation, built atop Qwen3-VL.

Jun 30, 2026
Vision-Language
GELab-Zero-4B (preview)
MuScriptor/MusicRuns anywhere

MuScriptor Large Turns Real Music Into MIDI

A new open model tackles multi-instrument transcription of real audio mixes, converting songs directly into editable MIDI.

Jun 30, 2026
Music
MuScriptor Large
Meituan/Text / LLMDatacenter

Meituan releases LongCat-2.0 language model

The Chinese delivery giant continues its push into open AI with a new text model on Hugging Face.

Jun 30, 2026
Text / LLM
LongCat-2.0
Monday, June 29, 2026

2 releases

Google DeepMind/Any-to-Any

Google DeepMind Releases TabFM for Tabular Data

A new foundation model brings zero-shot, in-context learning to classification and regression on structured tables.

Jun 29, 2026
Any-to-Any
TabFM 1.0.0
SenseTime/Any-to-AnyRuns on a laptop

SenseTime's SenseNova-Vision-7B-MoT Goes Any-to-Any

A single 7B model from SenseTime folds vision-language understanding, image generation, editing, and perception into one system.

Jun 29, 2026
Any-to-AnyVision-Language
SenseNova-Vision-7B-MoT
Saturday, June 27, 2026

2 releases

DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model

The new flagship arrives as a mixture-of-experts system with FP8 weights and open reasoning capabilities under a permissive license.

Jun 27, 2026
Text / LLMReasoning
DeepSeek-V4-Pro
DeepSeek/Text / LLMMulti-GPU server

DeepSeek Releases V4-Flash for Low-Latency Inference

A lighter, faster member of DeepSeek's V4 line arrives on Hugging Face under a permissive MIT license.

Jun 27, 2026
Text / LLM
DeepSeek V4.1 Flash
Thursday, June 25, 2026

1 release

Deepreinforce Ai/Text / LLMConsumer GPU

DeepReinforce Releases Ornith 1.0, a 35B Reasoning Model

The new dense model ships in GGUF format under a permissive MIT license, aimed at local and self-hosted deployment.

Jun 25, 2026
Text / LLMReasoning
Ornith-1.5-122B
Wednesday, June 24, 2026

3 releases

LiquidAI/Text / LLMRuns anywhere

Liquid AI's LFM2.5-230M targets on-device language tasks

A 230-million-parameter multilingual model built to run efficiently at the edge rather than in the cloud.

Jun 24, 2026
Text / LLM
LFM2.5 230M
NVIDIA/Text / LLMWorkstation GPU

NVIDIA's Nemotron 3 Puzzle Runs Big on a Lean Budget

A 75-billion-parameter mixture-of-experts reasoning model that activates just 9 billion parameters per token.

Jun 24, 2026
Text / LLMReasoning
Nemotron-Labs-3-Puzzle-75B-A9B
NVIDIA/Text / LLMWorkstation GPU

NVIDIA's Nemotron-3 Puzzle Brings a Lean MoE to Reasoning

The 75B-parameter model activates just 9B per token and ships in NVIDIA's NVFP4 format for efficient inference.

Jun 24, 2026
Text / LLMReasoning
Nemotron-3 Puzzle 75B-A9B
Tuesday, June 23, 2026

1 release

Deepreinforce Ai/Text / LLMMulti-GPU server

DeepReinforce debuts Ornith-1.0, a 397B MoE model

The flagship of a new open model family arrives under a permissive MIT license, with reasoning among its stated strengths.

Jun 23, 2026
Text / LLMReasoning
Ornith-1.5-122B
Monday, June 22, 2026

5 releases

Tencent/Image EditingRuns anywhere

Tencent's Moebius packs inpainting into 0.2B params

A lightweight image-editing framework claims results rivaling 10B-scale models, and it's already running in the browser.

Jun 22, 2026
Image Editing
Qwen · Alibaba/Text / LLMConsumer GPU

Qwen's AgentWorld Simulates Worlds for AI Agents

Alibaba's new MoE model acts as a language world model, generating the environments that agents act within.

Jun 22, 2026
Text / LLMReasoning
Qwen-AgentWorld-35B-A3B
Baidu/Vision-Language

Baidu's PP-OCRv6 packs 50-language OCR into tiny models

The latest release of PaddlePaddle's optical character recognition suite spans models from 1.5M to 34.5M parameters under an Apache 2.0 license.

Jun 22, 2026
Vision-Language
nineninesix/Text → SpeechRuns anywhere

Gepard 1.0 brings bilingual TTS with voice cloning

An open, autoregressive text-to-speech model targets English and Spanish under a permissive Apache 2.0 license.

Jun 22, 2026
Text → Speech
Gepard 1.0
InternScience/ReasoningConsumer GPU

Agents-A1: A 35B MoE Built for Agentic Scaling

InclusionAI's new mixture-of-experts model bets that agent-horizon scaling can rival far larger systems on long-running tasks.

Jun 22, 2026
ReasoningText / LLM
Agents-A1
Sunday, June 21, 2026

2 releases

Deepreinforce Ai/Text / LLMRuns anywhere

DeepReinforce's Ornith-1.0-9B Targets Agentic Coding

A compact, MIT-licensed 9B model built for autonomous coding tasks arrives on Hugging Face.

Jun 21, 2026
CodeText / LLM
Ornith-1.5-122B
Deepreinforce Ai/Text / LLMRuns anywhere

Ornith-1.0-35B brings a mid-size MoE to agentic coding

An MIT-licensed mixture-of-experts model targets self-scaffolding code tasks without the footprint of a frontier system.

Jun 21, 2026
CodeText / LLM
Ornith-1.5-122B
Saturday, June 20, 2026

1 release

Poolside/CodeConsumer GPU

Poolside releases Laguna XS 2.1 code model

The compact, code-focused language model arrives on Hugging Face under an open model license.

Jun 20, 2026
CodeText / LLM
Laguna-XS-2.1
Friday, June 19, 2026

2 releases

Datalab To/Vision-LanguageRuns on a laptop

LIFT: A Qwen3.5-Based VLM for PDF-to-JSON Extraction

Datalab's new open vision-language model targets structured data extraction from documents, turning messy PDFs into clean JSON.

Jun 19, 2026
Vision-Language
LIFT
Baidu/Vision-LanguageRuns anywhere

Baidu releases Unlimited-OCR under permissive MIT license

The Chinese tech giant's multilingual vision-language model targets text extraction across languages and document types.

Jun 19, 2026
Vision-Language
Unlimited-OCR
Thursday, June 18, 2026

3 releases

Cohere/Speech → TextRuns anywhere

Cohere releases Apache-licensed Arabic speech model

The Cohere Labs transcription model targets Arabic and English audio under a permissive open license.

Jun 18, 2026
Speech → Text
Cohere Transcribe Arabic
Krea/Text → ImageRuns on a laptop

Krea 2 Arrives as Open-Weights Text-to-Image Model

The image-generation startup releases its second-generation diffusion model in raw and turbo variants under open weights.

Jun 18, 2026
Text → Image
Krea 2
Krea/Text → ImageMajor releaseRuns on a laptop

Krea 2 Arrives as a 12B Open-Weights Image Model

A new text-to-image model ships with a faster Turbo variant and downloadable weights on Hugging Face.

Jun 18, 2026
Text → Image
Krea 2
Wednesday, June 17, 2026

1 release

Zhipu AI/Text / LLMMajor releaseDatacenter

Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model

The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.

Jun 17, 2026
Text / LLMReasoning
GLM-5.3
Tuesday, June 16, 2026

2 releases

Owensong/Text → Speech

Resemble AI's Inflect-Nano-v1 puts TTS on local hardware

An ultra-small, experimental text-to-speech model arrives under Apache 2.0, aimed at running speech synthesis directly on local machines.

Jun 16, 2026
Text → Speech
Inflect-Nano-v1
Boogu/Image EditingRuns on a laptop

Boogu-Image 0.1 Edit arrives with Apache license

A new open-weight diffusion model for image editing ships with ComfyUI support and a permissive license that allows commercial use.

Jun 16, 2026
Image Editing
Boogu-Image 0.1 Edit
Monday, June 15, 2026

1 release

Poolside/Text / LLMMulti-GPU server

Poolside Releases Laguna-M.1, an Open MoE Model

The AI coding startup steps into open weights with an Apache-2.0 mixture-of-experts model built for text and code.

Jun 15, 2026
Text / LLMCode
Laguna-M.1
Sunday, June 14, 2026

1 release

Microsoft/Text / LLMRuns on a laptop

Microsoft's FastContext is a 4B sub-agent for code

A compact Qwen3-derived model built to explore repositories, released under a permissive MIT license.

Jun 14, 2026
Text / LLMCode
FastContext 1.0 4B SFT
Saturday, June 13, 2026

1 release

Moonshot AI/Text / LLMMajor releaseDatacenter

Moonshot AI releases Kimi K3, a 2.8T-parameter MoE model

The open-weights multimodal model leans into coding and agentic tasks, extending Moonshot's Kimi line into a new scale bracket.

Jun 13, 2026
Text / LLMVision-Language
Kimi K3
Friday, June 12, 2026

1 release

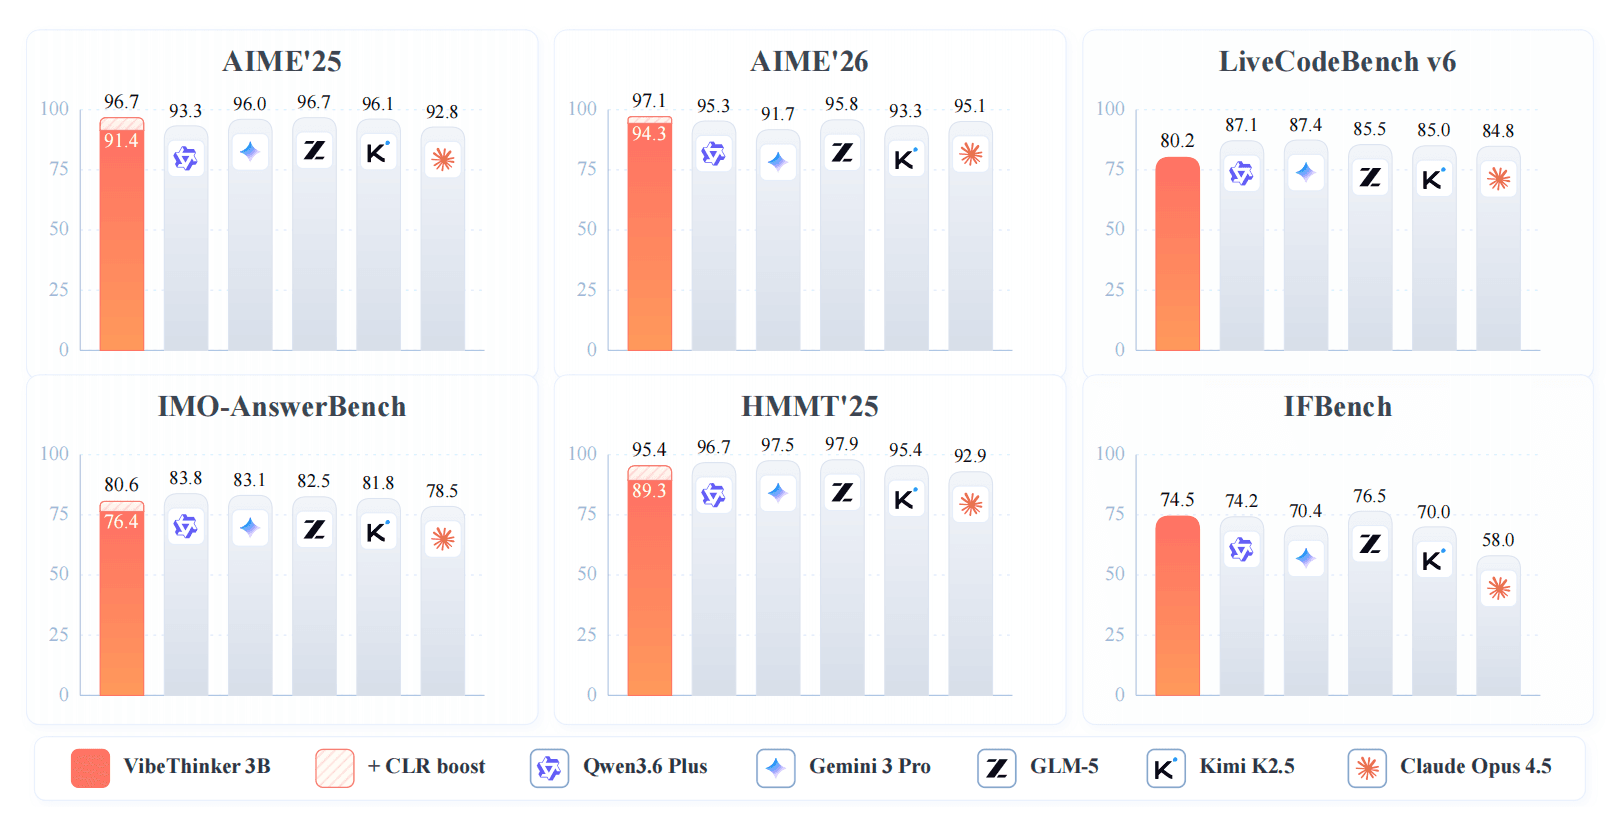
WeiboAI/ReasoningRuns anywhere

Weibo AI Releases VibeThinker-3B, a Compact Reasoning Model

The new 3-billion-parameter model from the Chinese tech giant focuses on challenging benchmarks in mathematics, coding, and graduate-level questions.

Jun 12, 2026
ReasoningText / LLM
VibeThinker-3B
Thursday, June 11, 2026

2 releases

Moonshot AI/CodeMajor releaseDatacenter

Moonshot AI Releases Kimi, a Multimodal Coding Model

The new Mixture-of-Experts model from the Chinese AI company can generate code while also understanding visual inputs, a rare combination in open models.

Jun 11, 2026
CodeVision-Language
Kimi-K2.7-Code
Zyphra/Text → Speech

Zyphra Releases Open-Source Zonos 2 TTS Model

The new text-to-speech model offers a commercially permissive alternative for developers in a field still dominated by closed-source APIs.

Jun 11, 2026
Text → Speech
Zonos 2
Tuesday, June 9, 2026

3 releases

Google DeepMind/Text / LLMConsumer GPU

Google Releases Open-Source DiffusionGemma 26B Model

The new 26B parameter model from DeepMind uses a diffusion-based architecture, a technique more common in image generation, to produce text.

Jun 9, 2026
Text / LLMVision-Language
DiffusionGemma
Zhipu AI/Image → Video

Zhipu AI Releases SCAIL-2 for Character Animation

The new open-source diffusion model from the company's research arm generates video clips from a single character image and a sequence of poses.

Jun 9, 2026
Image → Video
SCAIL-2
Baidu/Vision-LanguageRuns anywhere

PaddleOCR's PP-OCRv6 Adds a Medium Detection Model

Baidu's open-source OCR toolkit ships an Apache-licensed text-line detector in safetensors format, tuned for a balance of accuracy and speed.

Jun 9, 2026
Vision-Language
PP-OCRv6 Medium Detection
Friday, June 5, 2026

1 release

Cohere/CodeConsumer GPU

Cohere Releases North-Mini-Code, an Open MoE Model

The new Apache 2.0-licensed model is designed for code generation and agentic chat applications, using a Mixture-of-Experts architecture for efficiency.

Jun 5, 2026
CodeText / LLM
North-Mini-Code 1.0
Thursday, June 4, 2026

3 releases

Bosonai/Text → SpeechRuns on a laptop

Boson AI releases Higgs TTS v3, a 4B speech model

The new open-weights text-to-speech system targets expressive, controllable voice generation across multiple languages with built-in voice cloning.

Jun 4, 2026
Text → Speech
Higgs TTS v3 4B
Bosonai/Text → SpeechRuns on a laptop

Higgs TTS 3 lands as a 4B multilingual speech model

Boson AI's new text-to-speech release aims for expressive, controllable voice synthesis across multiple languages.

Jun 4, 2026
Text → Speech
Higgs TTS 3 4B
Bosonai/Text → SpeechRuns on a laptop

Boson AI's Higgs Audio v3 Offers Expressive, Multilingual TTS

The new 4-billion-parameter text-to-speech model is available for non-commercial use, promising fine-grained control over vocal delivery.

Jun 4, 2026
Text → Speech
Higgs Audio v3 TTS 4B
Wednesday, June 3, 2026

2 releases

Stability AI/Text → ImageRuns on a laptop

Ideogram 4.0 arrives as an open-weight image model

A 9.3-billion-parameter text-to-image system lands with open weights and a public GitHub home.

Jun 3, 2026
Text → Image
Black Forest Labs/Text → ImageRuns on a laptop

Ideogram 4.0 arrives as an open-weight image model

A 9.3-billion-parameter text-to-image model lands on GitHub with downloadable weights and code.

Jun 3, 2026
Text → Image
Tuesday, June 2, 2026

2 releases

MiniMax/Vision-LanguageMajor releaseMulti-GPU server

MiniMax Releases M3, a Multimodal MoE Model

The new open-weight model from MiniMax AI combines vision, coding, and reasoning using a Mixture-of-Experts architecture.

Jun 2, 2026
Vision-LanguageAny-to-Any
MiniMax-M3
JD/Text → VideoConsumer GPU

JD.com Enters Open-Source AI Video with JoyAI-Echo

The Chinese e-commerce giant has released a new model capable of generating long-form, multi-shot videos with synchronized audio from text prompts.

Jun 2, 2026
Text → Video
JoyAI-Echo
Saturday, May 30, 2026

1 release

Ideogram Ai/Text → ImageRuns on a laptop

Ideogram 4.0: A 9.3B Open-Weight Text-to-Image Model

The new 9.3 billion parameter model uses a Diffusion Transformer architecture and excels at rendering coherent text within generated images.

May 30, 2026
Text → Image
Ideogram 4.0
Friday, May 29, 2026

1 release

Baidu/Text → Video

Baidu Releases NAVA for Text-to-Video with Audio

The new model from the Chinese tech giant uses a Multimodal Diffusion Transformer to generate synchronized audio and video from text or image prompts.

May 29, 2026
Text → Video
NAVA
Wednesday, May 27, 2026

1 release

Stability AI/Music

Stability AI's Demon brings real-time music diffusion to local GPUs

An open-source engine generates audio on the fly at 25Hz, no cloud required.

May 27, 2026
Music
Monday, May 25, 2026

1 release

OpenMOSS/Text → SpeechRuns on a laptop

MOSS-TTS Aims for More Robust Speech Synthesis

A new text-to-speech model introduces 'delay-pattern decoding' to solve common word skipping and repetition errors in parallel generation.

May 25, 2026
Text → Speech
MOSS-TTS v1.5
Saturday, May 23, 2026

2 releases

Google DeepMind/Any-to-AnyMajor releaseRuns on a laptop

Google Releases Gemma 4 12B Multimodal Model

The new 12-billion-parameter open model from DeepMind introduces a unified 'any-to-any' architecture for advanced multimodal tasks.

May 23, 2026
Any-to-AnyVision-Language
Gemma 4
Google DeepMind/Any-to-AnyMajor releaseRuns on a laptop

Google Releases Gemma 4, a 12B 'Any-to-Any' Model

The new 12-billion-parameter model from Google DeepMind is designed to handle a flexible mix of data types, moving beyond traditional text and image inputs.

May 23, 2026
Any-to-AnyVision-Language
Gemma 4
Thursday, May 21, 2026

5 releases

NVIDIA/Image → VideoWorkstation GPU

NVIDIA Releases Cosmos3 Image-to-Video World Model

The latest release in NVIDIA's 'world model' research family aims to generate coherent and realistic video from a single static image.

May 21, 2026
Image → Video
Cosmos3 Super Image2Video
Meituan/Image → Video

Meituan releases LongCat-Video-Avatar 1.5

An audio-driven avatar model that animates still images into talking video, with support for continuation of longer clips.

May 21, 2026
Image → Video
LongCat-Video-Avatar 1.5
OpenBMB/Text / LLMRuns anywhere

OpenBMB's MiniCPM5-1B targets on-device AI

The compact 1B-parameter model brings long-context handling and tool-calling to phones and laptops.

May 21, 2026
Text / LLM
MiniCPM5-2B
KRAFTON/Text → SpeechRuns anywhere

KRAFTON releases 1B zero-shot voice-cloning TTS

Raon-OpenTTS-1B is a flow-matching diffusion transformer that clones English voices from short reference clips.

May 21, 2026
Text → Speech
Raon-OpenTTS-1B
MisoLabs/Text → SpeechRuns on a laptop

MisoLabs Debuts MisoTTS, an Open Voice Model

The new text-to-speech system adapts the decoder-only architecture of language models like Llama to generate more natural-sounding speech.

May 21, 2026
Text → Speech
MisoTTS
Tuesday, May 19, 2026

2 releases

zhifeixie/Speech → TextRuns anywhere

Mega-ASR Improves on Qwen for Speech Recognition

Researcher Zhifei Xie has released a 1.7B-parameter model that refines Alibaba's Qwen3-ASR, showing improved performance on English and Chinese transcription benchmarks.

May 19, 2026
Speech → Text
Mega-ASR
OpenMOSS/Speech → TextRuns anywhere

OpenMOSS Releases Transcribe-Diarize ASR Model

The open-weights team behind MOSS turns to long-form speech recognition with built-in speaker diarization and timestamps.

May 19, 2026
Speech → Text
MOSS Transcribe-Diarize
Monday, May 18, 2026

1 release

NVIDIA/Image → Video

NVIDIA Releases SANA, a Camera-Controllable Video Model

The new model, SANA-WM, uses a bidirectional diffusion process to give creators fine-grained control over camera movement and video editing.

May 18, 2026
Image → VideoText → Video
SANA-WM Bidirectional
Friday, May 15, 2026

2 releases

NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Nemotron-3.5 Streaming ASR Model

The 600-million-parameter model uses a FastConformer architecture for real-time, multilingual speech-to-text applications.

May 15, 2026
Speech → Text
Nemotron 3.5 ASR Streaming 0.6B
ByteDance/Any-to-AnyMajor releaseRuns anywhere

ByteDance Releases Lance, a Unified Generative AI Model

The 3-billion-parameter model handles image and video generation, editing, and understanding from a single set of weights under a permissive license.

May 15, 2026
Any-to-AnyText → Image
Lance
Thursday, May 14, 2026

1 release

SenseTime/Any-to-AnyRuns on a laptop

SenseTime Releases 8B 'Any-to-Any' Infographic Model

The new 8B-parameter SenseNova U1 model from SenseTime is designed for complex multimodal tasks, including the in-conversation generation and editing of infographics.

May 14, 2026
Any-to-AnyText → Image
SenseNova U1 8B MoT Infographic
Tuesday, May 12, 2026

2 releases

OpenBMB/Text / LLM

GLiGuard: A Sub-1B Model for Faster LLM Guardrails

The team behind GLiNER releases an open-source small language model aimed at making safety moderation cheaper and quicker to run.

May 12, 2026
Text / LLM
OpenBMB/CodeRuns anywhere

Needle: A 26M-Parameter Model Built for Tool Calling

Cactus Compute distilled Gemini's tool-calling behavior into a tiny model meant to run locally.

May 12, 2026
CodeText / LLM
Monday, May 11, 2026

2 releases

Lightricks/Image → Video

Lightricks Releases LoRA for AI Lip-Dubbing

The new 'Identity-Control' adapter fine-tunes the company's LTX-2.3 video model to create realistic lip-syncing for dubbing workflows.

May 11, 2026
Image → VideoText → Video
LTX-2.5
Tencent/Text / LLMRuns anywhere

Tencent Releases 1.8B Model for Multilingual Translation

The 1.8 billion-parameter model from the Chinese tech giant is designed for high-quality translation across a wide range of language pairs.

May 11, 2026
Text / LLM
Hunyuan-MT2 1.8B
Wednesday, May 6, 2026

1 release

Supertone/Text → Speech

Supertone Releases On-Device Multilingual TTS Model

The new Supertonic 3 model supports seven languages and is optimized for local inference with the portable ONNX format.

May 6, 2026
Text → Speech
Supertonic 3
Tuesday, May 5, 2026

1 release

LiquidAI/EmbeddingsRuns anywhere

Liquid AI ships a 350M multilingual embedding model

LFM2.5-Embedding-350M targets retrieval and search workloads on edge hardware, where compact size matters as much as accuracy.

May 5, 2026
Embeddings
LFM2.5-24B-A2B
Sunday, May 3, 2026

1 release

Moonshot AI/Vision-LanguageMajor release

Kimi K2.6 tops closed models in coding test

Moonshot AI's open-weights mixture-of-experts model reportedly outperformed Claude, GPT-5.5, and Gemini on a programming challenge.

May 3, 2026
CodeText / LLM
Tuesday, April 28, 2026

1 release

NVIDIA/Image Editing

NVIDIA Releases PiD for High-Quality Image Upscaling

The new component is a specialized VAE decoder that works with Stability AI's Z-Image model to enhance super-resolution tasks.

Apr 28, 2026
Image Editing
NVIDIA PiD (Pixel Diffusion Decoder)
Friday, April 24, 2026

1 release

NVIDIA/Any-to-AnyRuns on a laptop

NVIDIA Releases Efficient Nemotron-3 Multimodal MoE

The new 30-billion parameter Mixture-of-Experts model handles text and images while using only 3 billion active parameters for inference.

Apr 24, 2026
Any-to-AnyReasoning
Nemotron-3 Nano Omni 30B-A3B Reasoning
Thursday, April 23, 2026

5 releases

Google DeepMind/Any-to-AnyConsumer GPU

Google Releases Gemma 4 Multimodal Open Model

The new 26-billion-parameter model from DeepMind uses a mixture-of-experts design for greater efficiency and is tuned for assistant-style tasks.

Apr 23, 2026
Any-to-AnyText / LLM
Gemma 4 26B-A4B Instruct (MoE)
Google DeepMind/Any-to-AnyMajor releaseConsumer GPU

Google Releases Multimodal Gemma 4 31B Model

The new 31-billion-parameter model is an instruction-tuned, 'any-to-any' powerhouse released under a permissive Apache 2.0 license.

Apr 23, 2026
Any-to-AnyText / LLM
Gemma 4
Google DeepMind/Any-to-AnyRuns anywhere

Google Releases 4B Multimodal Gemma 4 Assistant

The new 4-billion-parameter model is instruction-tuned for 'any-to-any' tasks, handling a flexible mix of data types.

Apr 23, 2026
Any-to-AnyText / LLM
Gemma 4 E4B-it Assistant
Google DeepMind/Any-to-AnyRuns anywhere

Google Releases 2B Multimodal Gemma 4 Assistant Model

The new compact model from DeepMind is instruction-tuned for "any-to-any" tasks, capable of processing and generating mixed data types.

Apr 23, 2026
Any-to-AnyText / LLM
Gemma 4 E2B-it Assistant
Xiaomi/Speech → TextRuns on a laptop

Xiaomi Releases MiMo Model for Speech Recognition

The new open-source model from the Chinese tech giant offers automatic speech recognition for Mandarin, Cantonese, and English under a permissive MIT license.

Apr 23, 2026
Speech → Text
MiMo-V2.5-ASR
Wednesday, April 22, 2026

4 releases

inclusionAI/Any-to-AnyRuns on a laptop

LLaDA2.0-Uni: A Unified MoE for Vision Tasks

The new open-source model from inclusionAI uses a Mixture-of-Experts architecture to handle multiple vision tasks in a single, diffusion-based system.

Apr 22, 2026
Any-to-AnyText → Image
LLaDA2.0-Uni
DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases V4-Pro, an Open MoE Contender

The new flagship model combines a Mixture-of-Experts architecture with a permissive MIT license, positioning it for wide commercial adoption.

Apr 22, 2026
Text / LLMReasoning
DeepSeek-V4-Pro
DeepSeek/Text / LLMMajor releaseMulti-GPU server

DeepSeek Releases V4-Flash, a Fast MIT-Licensed MoE Model

The new Mixture of Experts model from the Beijing-based AI lab is optimized for fast, efficient conversational AI and carries a fully permissive license.

Apr 22, 2026
Text / LLMReasoning
DeepSeek V4.1 Flash
SenseTime/Any-to-AnyRuns on a laptop

SenseTime Releases 8B Any-to-Any Multimodal Model

The new SenseNova-U1 model unifies image understanding, generation, and editing within a single 8-billion-parameter framework.

Apr 22, 2026
Any-to-AnyText → Image
SenseNova-U1.5-8B-MoT
Tuesday, April 21, 2026

1 release

Qwen · Alibaba/Vision-LanguageConsumer GPU

Alibaba's Qwen Releases Open 27B Vision Model

The new dense model, licensed under Apache 2.0, brings both text and image understanding to the midrange parameter space.

Apr 21, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Monday, April 20, 2026

1 release

NVIDIA/Any-to-AnyConsumer GPU

NVIDIA Releases Nemotron-3-Nano Omni-Modal MoE

The new 30-billion-parameter Mixture-of-Experts model handles any combination of modalities with just 3 billion active parameters.

Apr 20, 2026
Any-to-AnyReasoning
Nemotron-3 Nano Omni 30B-A3B Reasoning
Friday, April 17, 2026

1 release

Resemble AI/Text → Speech

Resemble AI Releases Dramabox Voice Cloning TTS Model

The new text-to-speech model uses a diffusion-transformer architecture for high-quality, expressive audio and one-shot voice cloning.

Apr 17, 2026
Text → Speech
Dramabox TTS
Thursday, April 16, 2026

1 release

IBM/Speech → TextRuns anywhere

IBM Releases 2B Granite Model for Multilingual Speech

The new two-billion-parameter model offers transcription capabilities for at least five major languages under a permissive Apache 2.0 license.

Apr 16, 2026
Speech → Text
Granite Speech 4.1 2B
Wednesday, April 15, 2026

1 release

Qwen · Alibaba/Vision-LanguageMajor releaseConsumer GPU

Qwen Releases 35B Multimodal Mixture-of-Experts Model

The new Qwen3.6-35B-A3B from Alibaba's Qwen team combines vision and language capabilities using an efficient sparse architecture.

Apr 15, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Tuesday, April 14, 2026

2 releases

Motif Technologies/Text → VideoRuns anywhere

Motif Releases 2B Open-Source Text-to-Video Model

The new Apache 2.0 licensed model uses a diffusion transformer architecture to offer a new open alternative for video generation research.

Apr 14, 2026
Text → VideoImage → Video
Motif-Video-2B
Moonshot AI/Vision-LanguageMajor releaseDatacenter

Moonshot AI Releases Kimi-K2.6 Multimodal Model

The Chinese AI lab has published weights for its new vision-language model, though a restrictive license limits its use to research applications.

Apr 14, 2026
Vision-LanguageText / LLM
Kimi K2.6
Monday, April 13, 2026

1 release

OpenBMB/Vision-LanguageRuns anywhere

OpenBMB Releases MiniCPM-V for On-Device Vision

The new open-source vision-language model is designed for high-resolution image understanding on mobile and edge devices.

Apr 13, 2026
Vision-Language
MiniCPM-V 4.7 35B-A3B
Saturday, April 11, 2026

2 releases

NVIDIA/Text / LLMConsumer GPU

NVIDIA's Nemotron TwoTower mixes diffusion and Mamba

A new 30B mixture-of-experts base model activates just 3B parameters per token and pairs a hybrid diffusion/Mamba design.

Apr 11, 2026
Text / LLM
Nemotron TwoTower 30B-A3B Base
NVIDIA/Text / LLMConsumer GPU

NVIDIA's Nemotron TwoTower is a MoE experiment

An experimental 30B mixture-of-experts base model blends diffusion and Mamba ideas under a two-tower design.

Apr 11, 2026
Text / LLM
Nemotron TwoTower 30B-A3B Base
Thursday, April 9, 2026

1 release

MiniMax/Text / LLMMulti-GPU server

MiniMax Releases M2.7, an MoE Model with FP8 Weights

The new conversational language model from the Chinese AI company uses a Mixture-of-Experts architecture and 8-bit weights, but is released under a restrictive custom license.

Apr 9, 2026
Text / LLMReasoning
MiniMax-M2.7
Tuesday, April 7, 2026

1 release

Baidu/Text → ImageRuns on a laptop

Baidu Releases 8B Text-to-Image Model ERNIE-Image

The large diffusion model from the Chinese tech giant is available under the commercially permissive Apache 2.0 license, a notable release for the community.

Apr 7, 2026
Text → Image
ERNIE-Image
Monday, April 6, 2026

1 release

Black Forest Labs/Text → ImageRuns anywhere

Black Forest Labs Releases Open FLUX.2 Image Decoder

This new component is part of a novel transformer-based architecture for text-to-image generation, released under a permissive Apache 2.0 license.

Apr 6, 2026
Text → ImageImage Editing
FLUX.2 small decoder
Friday, April 3, 2026

2 releases

Zhipu AI/Text / LLMMajor releaseDatacenter

Zhipu AI Releases Open-Source GLM-5.1 MoE Model

The new bilingual model from the Chinese AI firm features an efficient Mixture-of-Experts architecture and a fully permissive MIT license.

Apr 3, 2026
Text / LLMReasoning
GLM-5.3
OpenBMB/Text → SpeechRuns anywhere

OpenBMB Releases VoxCPM2 for Expressive TTS

The new diffusion-based model from the OpenBMB research group supports multilingual speech, emotional control, and zero-shot voice cloning.

Apr 3, 2026
Text → Speech
VoxCPM2
Thursday, April 2, 2026

2 releases

OpenMOSS/Text → SpeechRuns anywhere

MOSS-TTS-Nano Delivers Multilingual Speech at 100M Params

The new open-source model from OpenMOSS-Team generates high-quality speech in multiple languages while maintaining a remarkably small footprint.

Apr 2, 2026
Text → Speech
MOSS-TTS-Nano-100M
Tencent/Vision-LanguageRuns anywhere

Tencent Releases 2B Vision Model for Robotics

The new HY-Embodied 0.5 is a vision-language model designed specifically for multi-object tracking in dynamic, real-world environments.

Apr 2, 2026
Vision-Language
HY-Embodied 0.5
Tuesday, March 31, 2026

2 releases

Tencent/Image → Video

Tencent Releases HY-OmniWeaving for Multi-Image Video

Built on their HunyuanVideo-1.5 architecture, the new model synthesizes video by combining multiple static images and text prompts into a cohesive narrative.

Mar 31, 2026
Image → VideoText → Video
HY-OmniWeaving
JD/Image Editing

JD.com Releases Open-Source Bilingual Image Editor

The new JoyAI-Image-Edit model allows for instruction-based photo manipulation in both English and Chinese under a permissive Apache 2.0 license.

Mar 31, 2026
Image Editing
JoyAI-Image-Edit
Monday, March 30, 2026

2 releases

KRAFTON/Any-to-AnyRuns on a laptop

KRAFTON Releases 9B Bilingual Speech Model

The gaming giant behind 'PUBG' has released Raon-Speech-9B, a multimodal model for English and Korean speech recognition and synthesis.

Mar 30, 2026
Any-to-AnyText → Speech
Raon-Speech-9B
k2-fsa/Text → SpeechRuns anywhere

OmniVoice TTS Offers Zero-Shot Multilingual Voice Cloning

A new open-source text-to-speech model from the k2-fsa project can replicate a voice and generate speech in multiple languages from a single short audio sample.

Mar 30, 2026
Text → Speech
OmniVoice
Friday, March 27, 2026

1 release

HKUSTAudio/Any-to-Any

HKUST Releases Audio-Omni, a Unified Audio Model

The new diffusion-based model handles speech, music, and general audio tasks like conversion and editing within a single, versatile framework.

Mar 27, 2026
Any-to-AnyMusic
Audio-Omni
Wednesday, March 25, 2026

1 release

Meituan/Any-to-AnyWorkstation GPU

Meituan Releases LongCat-Next 'Any-to-Any' AI Model

The Chinese tech company has released the weights for a unified model that can process and generate combinations of text, images, audio, and video.

Mar 25, 2026
Any-to-AnyText / LLM
LongCat-Next
Tuesday, March 24, 2026

1 release

Cohere/Speech → TextRuns anywhere

Cohere Releases Top-Ranked Multilingual Transcription Model

The new automatic speech recognition model from Cohere Labs sets a new benchmark on the Hugging Face Open ASR Leaderboard for multilingual performance.

Mar 24, 2026
Speech → Text
Cohere Transcribe 03-2026
Monday, March 23, 2026

1 release

Aratako/Text → SpeechRuns anywhere

Irodori-TTS v2 Offers Open Japanese Speech Synthesis

The 500-million-parameter model from researcher Aratako provides a high-quality, single-speaker voice under a permissive MIT license.

Mar 23, 2026
Text → Speech
Irodori-TTS-500M v2
Saturday, March 21, 2026

1 release

GAIR/Image → Video

GAIR Releases daVinci-MagiHuman for Video Generation

The new open-source model from the General Artificial Intelligence Research team can create video clips complete with audio from a variety of inputs.

Mar 21, 2026
Image → VideoText → Video
daVinci-MagiHuman
Wednesday, March 18, 2026

1 release

Baidu/Vision-LanguageRuns on a laptop

Baidu Releases Qianfan-OCR for Document Intelligence

The new vision-language model from the Chinese tech giant is designed for complex, multilingual optical character recognition and layout analysis.

Mar 18, 2026
Vision-Language
Qianfan-OCR
Monday, March 16, 2026

1 release

Cactus Compute/CodeRuns anywhere

Needle: A 26M-Param Model Built for On-Device Tool Calls

Cactus Compute's tiny encoder-decoder is distilled specifically for function calling at the edge, trading general chat for a narrow, useful job.

Mar 16, 2026
Text / LLMCode
Needle
Wednesday, March 11, 2026

2 releases

Google DeepMind/Any-to-AnyMajor releaseConsumer GPU

Google Releases Gemma 4, a 26B Vision-Language Model

The new open-source model from DeepMind uses a Mixture-of-Experts architecture to handle both text and image inputs efficiently.

Mar 11, 2026
Vision-LanguageText / LLM
Gemma 4
Google DeepMind/Any-to-AnyMajor releaseConsumer GPU

Google Releases Multimodal Gemma 4 31B Model

The new 31-billion-parameter model is instruction-tuned and can process both text and images, marking a significant expansion for the Gemma family.

Mar 11, 2026
Vision-LanguageText / LLM
Gemma 4
Monday, March 9, 2026

2 releases

Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

Black Forest Labs Releases 9B FLUX.2 klein Image Model

The new open-weight model offers a more compact, distilled version of the advanced FLUX architecture for text-to-image and editing tasks.

Mar 9, 2026
Text → ImageImage Editing
FLUX.2 Klein 9B
Fishaudio/Text → SpeechRuns on a laptop

Fish Audio's S2-Pro Brings Expressive TTS to Open Source

The new text-to-speech model can follow natural language instructions to control tone, clone voices from short clips, and speak multiple languages.

Mar 9, 2026
Text → Speech
Fish Audio S2-Pro
Wednesday, March 4, 2026

1 release

Lightricks/Image → Video

Lightricks LTX-2.3 Generates Video and Audio Together

The new model, based on Stable Video Diffusion, can create video and a corresponding soundtrack simultaneously from text, image, or audio prompts.

Mar 4, 2026
Image → VideoText → Video
LTX-2.5
Monday, March 2, 2026

6 releases

NVIDIA/Vision-LanguageRuns anywhere

NVIDIA's New 3B VLM Pinpoints Objects in Images

The new 3-billion-parameter model, based on the company's Eagle architecture, is designed for high-precision visual grounding tasks.

Mar 2, 2026
Vision-Language
LocateAnything-3B
Google DeepMind/Any-to-AnyMajor releaseRuns anywhere

Google Releases Compact Gemma 4 E2B Multimodal Model

The new 2-billion-parameter model from Google DeepMind brings efficient image-and-text understanding to the open-source Gemma family.

Mar 2, 2026
Any-to-AnyVision-Language
Gemma 4 E2B
Google DeepMind/Any-to-AnyMajor releaseRuns anywhere

Google's Gemma 4 Arrives with Any-to-Any Multimodal Skills

The new 2-billion-parameter model from DeepMind can process text, vision, and audio, making it a versatile and efficient foundation for developers.

Mar 2, 2026
Any-to-AnyVision-Language
Gemma 4 E2B
Google DeepMind/Any-to-AnyRuns on a laptop

Google Releases Gemma 4 E4B, a 4B Multimodal Model

The new 4-billion-parameter vision-language model brings image and text understanding to Google's popular open-source family.

Mar 2, 2026
Any-to-AnyVision-Language
Gemma 4 E4B
Google DeepMind/Any-to-AnyMajor releaseRuns on a laptop

Google's Gemma 4 Debuts with Any-to-Any Multimodality

The new 4-billion parameter model from Google DeepMind is designed for versatile input and output, handling text, images, and other data types.

Mar 2, 2026
Any-to-AnyVision-Language
Gemma 4 E4B
Xiaomi/Image EditingConsumer GPU

Xiaomi Releases Bilingual Image Editing Model FireRed 1.1

The new open-source model from Xiaomi's FireRedTeam leverages the Qwen-Image-Edit pipeline to offer instruction-based image editing in both English and Chinese.

Mar 2, 2026
Image Editing
FireRed Image Edit 1.1
Saturday, February 28, 2026

1 release

Qwen · Alibaba/Vision-LanguageRuns anywhere

Alibaba's Qwen Releases Compact 0.8B Vision Model

The new 800-million-parameter model is the smallest in the Qwen3.5 family, designed for efficient multimodal tasks on consumer-grade hardware.

Feb 28, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Friday, February 27, 2026

3 releases

IBM/Speech → TextRuns anywhere

IBM Releases 1B Granite Model for Multilingual Speech

The new Apache 2.0-licensed model is part of the company's Granite family and aims to provide high-quality speech-to-text across several languages.

Feb 27, 2026
Speech → Text
Granite 4.0 1B Speech
Qwen · Alibaba/Vision-LanguageRuns on a laptop

Alibaba's Qwen team releases 4B vision-language model

The new Qwen3.5-4B model combines text and image understanding in a compact, permissively licensed package for developers.

Feb 27, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Qwen · Alibaba/Vision-LanguageRuns on a laptop

Qwen Releases 9B Multimodal Model in New 3.5 Series

The new open-source vision-language model from Alibaba's Qwen team offers strong performance in a compact, Apache 2.0-licensed package.

Feb 27, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Tuesday, February 24, 2026

4 releases

Resemble AI/Speech → Text

Moonshine: Open STT Models Aim to Beat Whisper

Resemble AI releases MIT-licensed speech-to-text models that claim higher accuracy than OpenAI's Whisper Large v3.

Feb 24, 2026
Speech → Text
Qwen · Alibaba/Vision-LanguageMajor releaseWorkstation GPU

Qwen Releases Flagship 122B Multimodal MoE Model

The new Qwen3.5-122B-A10B combines a massive parameter count with an efficient Mixture-of-Experts architecture for advanced vision and language tasks.

Feb 24, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Qwen · Alibaba/Vision-LanguageMajor releaseConsumer GPU

Qwen Releases 27B Vision Model with Long Context

The new model from Alibaba's Qwen team combines multimodal understanding with a 131K token context window under a permissive Apache 2.0 license.

Feb 24, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Qwen · Alibaba/Vision-LanguageConsumer GPU

Qwen Releases Efficient 35B Multimodal MoE Model

The new Qwen3.5-35B-A3B model from Alibaba combines vision and language capabilities with a resource-friendly Mixture of Experts design.

Feb 24, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
Monday, February 16, 2026

2 releases

Qwen · Alibaba/Vision-LanguageMajor releaseMulti-GPU server

Qwen releases flagship 397B multimodal MoE

The new open-source model from Alibaba uses a Mixture-of-Experts architecture to balance massive scale with efficient inference.

Feb 16, 2026
Vision-LanguageText / LLM
Qwen3.8-27B
HumeAI/Text → SpeechRuns on a laptop

Hume AI Releases 3B Multilingual Text-to-Speech Model

The new model, Tada-3B-ML, is designed for fine-grained control over vocal expression across more than 10 languages.

Feb 16, 2026
Text → Speech
Tada-3B-ML
Thursday, February 12, 2026

2 releases

nineninesix/Text → SpeechRuns anywhere

Kani-TTS-2 Offers New Open-Source Voice Generation

An independent researcher has released a new English text-to-speech model under a permissive license, built on a modern generative foundation.

Feb 12, 2026
Text → Speech
Kani-TTS-2 (English)
MiniMax/Text / LLMMulti-GPU server

MiniMax Releases M2.5 Mixture-of-Experts Model

The Chinese AI company's first open-weight release uses an efficient FP8 data type but comes with a restrictive, non-commercial license.

Feb 12, 2026
Text / LLM
MiniMax-M2.7
Wednesday, February 11, 2026

1 release

Zhipu AI/Text / LLMMajor releaseDatacenter

Zhipu AI Releases Open-Source GLM-5 MoE Model

The new Mixture-of-Experts model from the Chinese AI company combines an advanced architecture with a fully permissive MIT license for commercial use.

Feb 11, 2026
Text / LLMReasoning
GLM-5.3
Tuesday, February 10, 2026

2 releases

inclusionAI/Any-to-AnyWorkstation GPU

inclusionAI's Ming 2.0 Tackles Any-to-Any Multimodality

The new open-source Mixture-of-Experts model can process and generate content across text, images, and audio in any combination.

Feb 10, 2026
Any-to-Any
Ming-flash-omni 2.0
Nanbeige/Text / LLMRuns anywhere

Nanbeige Releases 3B Chinese-Enhanced Language Model

The new Llama-based model was trained from scratch on 3.5 trillion tokens of Chinese and English data to enhance its bilingual capabilities.

Feb 10, 2026
Text / LLM
Nanbeige4.3-33B
Friday, February 6, 2026

2 releases

OpenMOSS/Text → SpeechRuns on a laptop

MOSS-TTS: A New Multilingual Text-to-Speech Model

The new system from the OpenMOSS Team uses a novel 'delay-pattern' architecture to generate natural-sounding speech in Chinese, English, and Japanese.

Feb 6, 2026
Text → Speech
MOSS-TTS
Soul AILab/Music

Soul-AILab Releases Zero-Shot Singing Voice Model

The new model, SoulX-Singer, can replicate a singing voice from a short audio sample and supports both English and Chinese under a permissive license.

Feb 6, 2026
MusicText → Speech
SoulX-Singer
Tuesday, February 3, 2026

1 release

OpenBMB/Any-to-AnyRuns on a laptop

OpenBMB Releases 'Any-to-Any' Multimodal Model

The new MiniCPM-o 4.5 model from the open-source research group can process and generate interleaved combinations of images, text, and audio.

Feb 3, 2026
Any-to-AnyVision-Language
MiniCPM-o 4.5
Monday, February 2, 2026

1 release

OpenBMB/Any-to-AnyRuns on a laptop

MiniCPM-o 4.5 Offers 'Any-to-Any' Multimodal AI

The new model from OpenBMB supports mixed-modality inputs and outputs, from text and images to audio and video, in a single efficient package.

Feb 2, 2026
Any-to-AnyVision-Language
MiniCPM-o 4.5
Friday, January 30, 2026

2 releases

Qwen · Alibaba/CodeWorkstation GPU

Qwen Releases Coder-Next, A New Open MoE Coding Model

The new model from Alibaba's Qwen team uses a Mixture-of-Experts architecture and is released under the commercially-friendly Apache 2.0 license.

Jan 30, 2026
CodeText / LLM
Qwen3-Coder-Next
Zhipu AI/Vision-LanguageRuns anywhere

Zhipu AI Releases Multilingual GLM-OCR Vision Model

The new vision-language model from the creators of the GLM series is specialized for recognizing and extracting text from images across multiple languages.

Jan 30, 2026
Vision-Language
GLM-OCR
Wednesday, January 28, 2026

7 releases

Black Forest Labs/Text → ImageRuns on a laptop

Black Forest Labs Releases FLUX.2 Klein 9B

The open-weight text-to-image model brings a 9-billion-parameter base release to the FLUX.2 Klein family.

Jan 28, 2026
Text → Image
OpenMOSS/Any-to-Any

OpenMOSS Releases MOVA, a 720p Multimodal Video Generator

The new open model can generate high-definition video with synchronized audio from a flexible combination of text and image prompts.

Jan 28, 2026
Any-to-AnyImage → Video
MOVA 720p
Baidu/Vision-LanguageRuns anywhere

Baidu Releases Open VLM for Advanced Document OCR

The new PaddleOCR-VL model is built to parse not just text, but also the tables, formulas, and page layouts found in complex documents.

Jan 28, 2026
Vision-Language
PaddleOCR-VL-1.5
OpenMOSS/Image → Video

OpenMOSS Releases MOVA for Joint Video and Audio Gen

The new model generates 360p video from text or images and creates corresponding audio tracks simultaneously, a notable step for integrated audiovisual synthesis.

Jan 28, 2026
Image → VideoText → Video
MOVA-360p
Qwen · Alibaba/Speech → TextRuns anywhere

Qwen Releases 0.6B Model for Audio-Text Alignment

The new open-source tool, based on the Qwen3 architecture, precisely synchronizes audio recordings with their corresponding text transcripts.

Jan 28, 2026
Speech → Text
Qwen3 ForcedAligner 0.6B
Qwen · Alibaba/Speech → TextRuns anywhere

Qwen3 Family Expands into Speech Recognition

Alibaba's Qwen team has released a new 1.7-billion-parameter model designed specifically for automatic speech recognition.

Jan 28, 2026
Speech → Text
Qwen3-ASR-1.7B
Qwen · Alibaba/Speech → TextRuns anywhere

Qwen open-sources compact model for speech recognition

The new 600-million-parameter Qwen3-ASR model is designed for efficient, high-quality audio transcription under a permissive license.

Jan 28, 2026
Speech → Text
Qwen3-ASR-1.7B
Tuesday, January 27, 2026

1 release

DeepSeek/Vision-LanguageRuns anywhere

DeepSeek-OCR-2 Tackles Multilingual Document AI

The new open vision-language model is designed to extract text and understand structure from complex, multilingual documents.

Jan 27, 2026
Vision-Language
DeepSeek-OCR-2
Monday, January 26, 2026

1 release

robbyant/Image → Video

Lingbot-World Animates Images with Camera Control

The new open-source world model from researcher robbyant generates short video clips from a single image, giving users control over the virtual camera path.

Jan 26, 2026
Image → Video
Lingbot World Base Cam
Friday, January 23, 2026

1 release

Qwen · Alibaba/Text → ImageRuns on a laptop

Alibaba's Qwen Team Releases Z-Image Diffusion Model

The makers of the popular Qwen language models have published their first open-source text-to-image generator with a permissive Apache 2.0 license.

Jan 23, 2026
Text → Image
Z-Image
Thursday, January 22, 2026

1 release

YatharthS/Text → Speech

LuxTTS Delivers Lightweight, Open-Source Speech Synthesis

The new text-to-speech model is optimized for the ONNX runtime, making it a promising option for efficient, on-device audio generation.

Jan 22, 2026
Text → Speech
LuxTTS
Wednesday, January 21, 2026

6 releases

Mistral AI/Speech → TextRuns on a laptop

Mistral Enters Speech AI with Voxtral Mini Model

The company, known for its powerful text models, has released its first open-source speech recognition system designed for real-time, multilingual transcription.

Jan 21, 2026
Speech → Text
Voxtral Mini 4B Realtime
Microsoft/Speech → TextRuns on a laptop

Microsoft Releases VibeVoice for Speech Transcription

The new open-source automatic speech recognition model handles multilingual transcription and speaker identification out of the box.

Jan 21, 2026
Speech → Text
VibeVoice ASR
Qwen · Alibaba/Text → SpeechRuns anywhere

Qwen Releases Open-Source Voice Cloning Model

The new 600-million-parameter Qwen3-TTS model can generate speech in multiple languages and clone voices from short audio clips.

Jan 21, 2026
Text → Speech
Qwen3-TTS 0.6B Base
Qwen · Alibaba/Text → SpeechRuns anywhere

Qwen Releases a Compact Custom-Voice TTS Model

The new 600-million-parameter model from Alibaba's Qwen team can clone voices from short audio clips for multilingual speech synthesis.

Jan 21, 2026
Text → Speech
Qwen3-TTS-12Hz-0.6B CustomVoice
Qwen · Alibaba/Text → SpeechRuns anywhere

Qwen Releases Open 1.7B Custom Voice Synthesis Model

Alibaba's Qwen team has released a new text-to-speech model capable of cloning voices from just a few seconds of audio.

Jan 21, 2026
Text → Speech
Qwen3-TTS 1.7B CustomVoice
Qwen · Alibaba/Text → SpeechRuns anywhere

Qwen Unveils Open Model for Custom Voice Synthesis

The new 1.7-billion-parameter text-to-speech model from Alibaba's Qwen team can generate novel voices from short audio prompts.

Jan 21, 2026
Text → Speech
Qwen3-TTS-12Hz-1.7B-VoiceDesign
Monday, January 19, 2026

1 release

Zhipu AI/Text / LLMConsumer GPU

Zhipu AI Releases GLM-4.7-Flash MoE Model

The new Mixture-of-Experts model from the Beijing-based AI company is optimized for speed and released under the permissive MIT license.

Jan 19, 2026
Text / LLM
GLM-4.7-Flash
Friday, January 16, 2026

1 release

LightOn/Vision-LanguageRuns anywhere

LightOn Releases OCR-2, a 1B Document AI Model

The new vision model from the Paris-based AI lab uses Mistral architecture to extract text and structure from complex documents like PDFs and forms.

Jan 16, 2026
Vision-Language
LightOnOCR-2 1B
Wednesday, January 14, 2026

6 releases

Black Forest Labs/Text → ImageRuns on a laptop

Black Forest Labs Releases 9B FLUX.2 Image Model

The new text-to-image model emphasizes speed and efficiency with a novel architecture and FP8 quantization.

Jan 14, 2026
Text → ImageImage Editing
FLUX.2 Klein 9B
ekwek/Text → SpeechRuns anywhere

Soprano TTS Model Leverages Qwen3 Architecture

The new 80-million-parameter text-to-speech model adapts a powerful language model architecture for efficient, open-source audio generation.

Jan 14, 2026
Text → Speech
Soprano-1.1-80M
Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

Black Forest Labs Releases Open-Source FLUX.2 Klein 4B

The new 4-billion-parameter model is a distilled version of the powerful FLUX.2 architecture, released under a commercially-friendly Apache 2.0 license.

Jan 14, 2026
Text → ImageImage Editing
FLUX.2 Klein 9B
Black Forest Labs/Text → ImageRuns on a laptop

FLUX.2 Klein: A Compact 4B Open-Source Image Model

The new 4-billion-parameter model from Black Forest Labs offers an efficient, transformer-based alternative to latent diffusion for image generation.

Jan 14, 2026
Text → ImageImage Editing
FLUX.2 Klein 9B
Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

Black Forest Labs Releases 9B FLUX.2 Image Model

The new 9-billion-parameter model uses a Diffusion Transformer architecture, promising higher performance than existing open-source alternatives.

Jan 14, 2026
Text → ImageImage Editing
FLUX.2 Klein 9B
Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

Black Forest Labs Releases New FLUX.2 Image Model

The new 9-billion-parameter text-to-image model uses a novel architecture that operates directly on pixels for faster, more efficient generation.

Jan 14, 2026
Text → ImageImage Editing
FLUX.2 Klein 9B
Monday, January 12, 2026

2 releases

HumeAI/Text → SpeechRuns anywhere

Hume AI Releases TADA 1B for Expressive Speech

The new 1-billion-parameter model combines a Llama 3.2 base with text-to-speech to generate more natural and nuanced audio.

Jan 12, 2026
Text → Speech
TADA 1B
Google DeepMind/Text / LLMRuns on a laptop

Google Releases TranslateGemma for Open Translation

The new 4B-parameter model is an instruction-tuned variant of Gemma, designed specifically for high-quality multilingual translation tasks.

Jan 12, 2026
Text / LLM
TranslateGemma 4B IT
Sunday, January 11, 2026

1 release

Kugelaudio/Text → SpeechRuns on a laptop

OpenMOSS Releases KugelAudio for European Languages

The new text-to-speech model uses a hybrid diffusion and autoregressive architecture for high-quality, multilingual synthesis.

Jan 11, 2026
Text → Speech
KugelAudio-0-open
Thursday, January 8, 2026

1 release

Zhipu AI/Text → ImageRuns on a laptop

Zhipu AI Releases Open, Bilingual GLM-Image Model

The new text-to-image model is fluent in both Chinese and English, built on the CogView2 architecture and released under a permissive MIT license.

Jan 8, 2026
Text → Image
GLM-Image
Wednesday, January 7, 2026

1 release

Google DeepMind/Vision-LanguageRuns on a laptop

Google's MedGemma brings open vision AI to medicine

The new 4-billion-parameter vision-language model is specialized for tasks in radiology, pathology, and complex clinical reasoning.

Jan 7, 2026
Vision-LanguageReasoning
MedGemma 1.5 4B IT
Tuesday, January 6, 2026

1 release

Supertone/Text → Speech

Supertone Open-Sources Supertonic 2 Voice Model

The new text-to-speech model from the audio AI company supports English, Korean, and Spanish and comes in the efficient ONNX format for deployment.

Jan 6, 2026
Text → Speech
Supertonic 2
Saturday, January 3, 2026

1 release

Lightricks/Image → VideoMajor releaseConsumer GPU

Lightricks Releases LTX-2 Multimodal Video Generator

The new diffusion model from the creative app company can generate short video clips from text, images, audio, and even other videos.

Jan 3, 2026
Image → VideoText → Video
LTX-2.5
Thursday, January 1, 2026

1 release

Moonshot AI/Vision-LanguageMajor releaseDatacenter

Moonshot AI Releases Kimi K2.5 Multimodal Model

The new vision-language model from the Chinese AI firm uses a Mixture-of-Experts architecture and is now available on Hugging Face.

Jan 1, 2026
Vision-LanguageText / LLM
Kimi K2.6
Tuesday, December 30, 2025

1 release

Qwen · Alibaba/Text → ImageConsumer GPU

Qwen Releases Bilingual Open-Source Image Model

Alibaba's latest text-to-image generator, Qwen-Image 2512, is optimized for creating visuals from both English and Chinese prompts.

Dec 30, 2025
Text → Image
Qwen-Image 2512
Tuesday, December 23, 2025

1 release

Qwen · Alibaba/Any-to-AnyRuns on a laptop

Qwen's Fun-Audio-Chat: An Open Speech-to-Speech LLM

The 8-billion-parameter model from Alibaba's Qwen team understands and generates spoken responses, enabling more natural audio-first applications.

Dec 23, 2025
Any-to-AnyText → Speech
Fun-Audio-Chat-8B
Saturday, December 20, 2025

1 release

MiniMax/Text / LLMMulti-GPU server

MiniMax Debuts M2.1, an MoE Model Optimized with FP8

The new Mixture of Experts model from the Chinese AI firm uses 8-bit floating-point precision for a smaller memory footprint and faster inference.

Dec 20, 2025
Text / LLM
MiniMax-M2.7
Thursday, December 18, 2025

1 release

Google DeepMind/Speech → TextRuns anywhere

Google Releases MedASR for Medical Transcription

The new speech recognition model from DeepMind is trained specifically on medical dictation, aiming for higher accuracy in clinical notes.

Dec 18, 2025
Speech → Text
MedASR
Wednesday, December 17, 2025

4 releases

YatharthS/Text → SpeechRuns anywhere

MiraTTS Brings Qwen2 to Bilingual Speech Synthesis

A new text-to-speech model from OpenMOSS leverages the Qwen2 architecture to generate speech in both English and Chinese.

Dec 17, 2025
Text → Speech
MiraTTS
ekwek/Text → SpeechRuns anywhere

Soprano-80M: A Tiny TTS Model Based on Qwen3

Developer 'ekwek' has released a compact 80-million-parameter text-to-speech model, notable for its unconventional use of a Qwen3 language model architecture.

Dec 17, 2025
Text → Speech
Soprano-80M
Qwen · Alibaba/Image EditingConsumer GPU

Qwen Releases Open, Bilingual Image Editing Model

The new diffusion model from Alibaba's team allows for precise, instruction-based image modifications in both English and Chinese.

Dec 17, 2025
Image Editing
Qwen-Image-Edit 2511
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Streaming Speech-to-Text Model

The 600-million-parameter Nemotron model is designed for real-time English transcription using a cache-aware FastConformer architecture.

Dec 17, 2025
Speech → Text
Nemotron Speech Streaming EN 0.6B
Monday, December 15, 2025

1 release

Qwen · Alibaba/Speech → Text

Qwen Releases Compact ASR Model for Streaming Audio

The new Fun-ASR-Nano model from Alibaba's team packs real-time multilingual transcription, speaker diarization, and hotword detection into an efficient package.

Dec 15, 2025
Speech → Text
Fun-ASR-Nano-2512
Saturday, December 13, 2025

1 release

Huaichang/Image → Video

PersonaLive Model Animates Portraits in Real Time

The new open-source model from OpenBMB uses a diffusion-based architecture to generate expressive video from a single still image.

Dec 13, 2025
Image → Video
PersonaLive
Friday, December 12, 2025

1 release

Tencent/Image → Video

Tencent's HY-WorldPlay Creates 3D Scenes from One Image

The new model from Tencent's Hunyuan team generates dynamic video and reconstructs 3D environments using a single static picture.

Dec 12, 2025
Image → VideoText → 3D
HY-WorldPlay
Thursday, December 11, 2025

1 release

Qwen · Alibaba/Text → SpeechRuns anywhere

Alibaba Releases CosyVoice 3 for Expressive TTS

The new 500-million-parameter text-to-speech model from the Qwen team offers multilingual voice cloning and emotional control.

Dec 11, 2025
Text → Speech
Fun-CosyVoice3-0.5B
Wednesday, December 10, 2025

1 release

Zhipu AI/Text → Speech

Zhipu AI Releases GLM-TTS for Zero-Shot Voice Cloning

This new text-to-speech model can replicate a voice from just a few seconds of audio, using a novel combination of flow matching and reinforcement learning.

Dec 10, 2025
Text → Speech
GLM-TTS
Tuesday, December 9, 2025

1 release

Zhipu AI/Speech → TextRuns anywhere

Zhipu AI Releases Compact Bilingual Speech Model

The new GLM-ASR-Nano model is designed for efficient automatic speech recognition in both English and Mandarin Chinese.

Dec 9, 2025
Speech → Text
GLM-ASR-Nano-2512
Sunday, December 7, 2025

1 release

Zhipu AI/Vision-LanguageRuns on a laptop

Zhipu AI Releases Fast, Open Vision Model GLM-4.6V-Flash

The new model from the GLM-4.6V family offers a fast, MIT-licensed option for developers working with both text and images.

Dec 7, 2025
Vision-Language
GLM-4.6V-Flash
Friday, December 5, 2025

2 releases

OpenBMB/Text → SpeechRuns anywhere

VoxCPM 1.5 Brings Open-Source Voice Cloning

The new 500-million-parameter text-to-speech model from OpenBMB supports both English and Chinese and can replicate a voice from a short audio sample.

Dec 5, 2025
Text → Speech
VoxCPM 1.5
Meituan/Image Editing

Meituan Releases Open, Bilingual Image Editing Model

The new LongCat-Image-Edit model follows natural language instructions to perform complex photo manipulations in both English and Chinese.

Dec 5, 2025
Image Editing
LongCat-Image-Edit
Thursday, December 4, 2025

2 releases

Quark Vision/Image → VideoRuns on a laptop

Baidu's Live-Avatar Animates Photos With Audio

The new 14-billion-parameter model uses audio input to generate realistic talking head videos from a single still image.

Dec 4, 2025
Image → Video
Live-Avatar
Microsoft/Text → SpeechRuns anywhere

Microsoft Releases VibeVoice for Real-Time AI Speech

The new 500-million-parameter model is designed for generating natural, long-form speech with very low latency for interactive applications.

Dec 4, 2025
Text → Speech
VibeVoice Realtime 0.5B
Tuesday, December 2, 2025

1 release

Resemble AI/Text → Speech

Resemble AI Releases Chatterbox Turbo for Open TTS

The new text-to-speech model focuses on performance and offers voice cloning capabilities for English under a permissive MIT license.

Dec 2, 2025
Text → Speech
Chatterbox Turbo
Monday, December 1, 2025

1 release

DeepSeek/Text / LLMDatacenter

DeepSeek-V3.2 Arrives With FP8 Weights, MIT License

The new Mixture-of-Experts model from DeepSeek AI combines an efficient FP8 architecture with a fully permissive license for commercial use.

Dec 1, 2025
Text / LLM
DeepSeek-V3.2
Friday, November 28, 2025

1 release

FlashLabs/Any-to-AnyRuns on a laptop

FlashLabs Releases Chroma-4B, an Any-to-Any Model

The new 4-billion-parameter model handles text, image, and speech inputs and outputs, including direct speech-to-speech translation.

Nov 28, 2025
Any-to-Any
Chroma-4B
Tuesday, November 25, 2025

1 release

Qwen · Alibaba/Text → ImageRuns on a laptop

Alibaba Releases Z-Image-Turbo, A Fast Open Image Model

The new text-to-image model from the team behind Qwen uses a diffusion transformer to generate high-resolution images in just a single step.

Nov 25, 2025
Text → Image
Z-Image-Turbo
Saturday, November 22, 2025

1 release

Black Forest Labs/Text → ImageMajor releaseWorkstation GPU

Black Forest Labs Releases Open-Source FLUX.2 Image Model

The developer preview of the next-generation text-to-image architecture promises significant architectural improvements over its predecessor.

Nov 22, 2025
Text → ImageImage Editing
FLUX.2 [dev]
Tuesday, November 18, 2025

2 releases

Tencent/Text → VideoMajor release

Tencent Releases HunyuanVideo 1.5 Generation Model

The new diffusion model generates short video clips from text and image prompts, adding another major player to the open video space.

Nov 18, 2025
Text → VideoImage → Video
HunyuanVideo 1.5
Tencent/Vision-LanguageRuns anywhere

Tencent Releases 1B Parameter HunyuanOCR Model

The new vision-language model from Tencent Hunyuan offers a compact, end-to-end solution for optical character recognition.

Nov 18, 2025
Vision-Language
HunyuanOCR
Monday, November 17, 2025

1 release

Mistral AI/Text → SpeechRuns on a laptop

Mistral AI Releases Voxtral, an Open-Source TTS Model

The French AI leader expands beyond large language models with a new, 4-billion-parameter model for generating multilingual speech.

Nov 17, 2025
Text → Speech
Voxtral 4B TTS
Saturday, November 15, 2025

1 release

Nari Labs/Text → SpeechRuns anywhere

Nari Labs Releases Dia2-2B, an Open Voice Cloning Model

The 2-billion-parameter text-to-speech model can clone voices from a short audio sample and is available under an Apache 2.0 license.

Nov 15, 2025
Text → Speech
Dia2-2B
Friday, November 7, 2025

2 releases

Meta AI/Vision-LanguageRuns anywhere

Meta releases SAM 3 for image and video segmentation

The latest Segment Anything Model extends Meta's mask-generation lineage from still images into video, now available on Hugging Face.

Nov 7, 2025
Vision-Language
SAM 3
Baidu/Vision-LanguageConsumer GPU

Baidu Releases Open Vision-Language MoE Model

The new ERNIE 4.5 VL model brings advanced multimodal reasoning to the open-source community with an efficient Mixture-of-Experts architecture.

Nov 7, 2025
Vision-LanguageReasoning
ERNIE 4.5 VL 28B A3B Thinking
Tuesday, November 4, 2025

1 release

Moonshot AI/ReasoningMajor releaseDatacenter

Moonshot AI Releases Kimi-K2 Reasoning Model

The new Mixture-of-Experts model is designed for complex tasks but arrives in a custom compressed format with a restrictive license.

Nov 4, 2025
ReasoningText / LLM
Kimi K2 Thinking
Friday, October 31, 2025

1 release

BAAI/Any-to-AnyConsumer GPU

BAAI Releases Emu3.5, an 'Any-to-Any' Multimodal Model

The new open-source model from the Allen Institute for AI unifies text and image understanding and generation into a single architecture.

Oct 31, 2025
Any-to-AnyVision-Language
Emu3.5
Thursday, October 30, 2025

1 release

Microsoft/Vision-LanguageRuns on a laptop

Microsoft Releases Fara-7B Vision Agent Model

The 7-billion-parameter model is designed to understand and interact with graphical user interfaces, building on Alibaba's open-source Qwen2.5-VL.

Oct 30, 2025
Vision-Language
Fara-7B
Monday, October 27, 2025

1 release

Soul AILab/Text → SpeechRuns anywhere

SoulX-Podcast 1.7B Offers Open Multi-Speaker TTS

The new 1.7 billion-parameter model from OpenMOSS is trained on conversational data to generate natural dialogue in English and Chinese.

Oct 27, 2025
Text → Speech
SoulX-Podcast 1.7B
Friday, October 24, 2025

1 release

Meituan/Text → Video

Meituan Releases Open-Source LongCat-Video Model

The Chinese tech giant has released a new MIT-licensed model capable of generating video from text, images, or by continuing existing clips.

Oct 24, 2025
Text → VideoImage → Video
LongCat-Video
Thursday, October 23, 2025

1 release

Meituan/Any-to-AnyDatacenter

Meituan Debuts LongCat-Flash-Omni, an Any-to-Any AI Model

The new open-source Mixture-of-Experts model can process and generate any combination of text, images, video, audio, and 3D data.

Oct 23, 2025
Any-to-Any
LongCat-Flash-Omni
Wednesday, October 22, 2025

2 releases

NVIDIA/Speech → Text

NVIDIA Releases Real-Time Speaker Diarization Model

The new Sortformer-based model is designed for streaming audio, identifying up to four distinct speakers in real time.

Oct 22, 2025
Speech → Text
Streaming Sortformer Diarization 4spk v2.1
MiniMax/Text / LLMMajor releaseMulti-GPU server

MiniMax Releases M2, an Open-Weight MoE for Agents

The Shanghai-based AI startup has released a new Mixture-of-Experts model focused on complex reasoning, coding, and agentic tasks.

Oct 22, 2025
Text / LLMReasoning
MiniMax-M2.7
Tuesday, October 21, 2025

1 release

Datalab To/Vision-LanguageRuns on a laptop

Datalab Releases Chandra, a New OCR Vision Model

The new vision-language model from Datalab is fine-tuned from Qwen2-VL to specialize in extracting text and structure from complex documents.

Oct 21, 2025
Vision-Language
Chandra OCR
Saturday, October 18, 2025

2 releases

Kuaishou/Any-to-Any

Kling Releases UniVideo for Generation and Understanding

The new open-source model combines both video generation and comprehension, a rare dual capability built on the Qwen2.5 vision-language foundation.

Oct 18, 2025
Any-to-AnyText → Video
UniVideo
Maya Research/Text → SpeechRuns on a laptop

Maya Research Releases Maya1, an Expressive TTS Model

The new Apache 2.0 licensed model uses a Llama-based architecture to generate more natural and emotionally nuanced speech from text.

Oct 18, 2025
Text → Speech
Maya1
Friday, October 17, 2025

1 release

DeepSeek/Vision-LanguageMajor releaseRuns anywhere

DeepSeek-OCR Tackles Document Parsing with Vision AI

The new vision-language model uses a novel context compression technique to efficiently extract text and structure from complex documents.

Oct 17, 2025
Vision-Language
DeepSeek-OCR
Thursday, October 16, 2025

1 release

Baidu/Vision-LanguageRuns anywhere

Baidu Releases PaddleOCR-VL for Document AI

The new vision-language model is fine-tuned to understand not just text, but the complex structure of tables, charts, and formulas.

Oct 16, 2025
Vision-Language
PaddleOCR-VL
Wednesday, October 15, 2025

1 release

NVIDIA/Speech → TextRuns anywhere

NVIDIA's Parakeet ASR Tackles Multi-Speaker Audio

The 600-million-parameter model offers real-time speech-to-text with speaker diarization, built on the efficient FastConformer architecture.

Oct 15, 2025
Speech → Text
Multitalker Parakeet Streaming 0.6B
Tuesday, October 14, 2025

1 release

inclusionAI/Any-to-AnyWorkstation GPU

inclusionAI Debuts 'Any-to-Any' Multimodal MoE Model

The new Ming-flash-omni-Preview aims to handle any combination of data modalities using an efficient Mixture of Experts architecture.

Oct 14, 2025
Any-to-Any
Ming-flash-omni-Preview
Saturday, October 11, 2025

1 release

Qwen · Alibaba/Vision-LanguageRuns on a laptop

Alibaba Releases Qwen3-VL, an 8B Open-Source Vision Model

The latest vision-language model from the popular Qwen series is instruction-tuned and available under an Apache 2.0 license.

Oct 11, 2025
Vision-Language
Qwen3-VL-8B-Instruct
Wednesday, October 8, 2025

3 releases

Google DeepMind/Text / LLMRuns anywhere

Google Releases Compact FunctionGemma Model

The new 270-million-parameter model from Google DeepMind is fine-tuned specifically for reliable function calling and tool use.

Oct 8, 2025
Text / LLM
FunctionGemma 270M IT
EPFL VITA/Image → Video

EPFL Releases SVI for Streaming Image-to-Video

The new open-source model from Swiss researchers uses a novel chunking method to generate indefinitely long videos from a single still image.

Oct 8, 2025
Image → Video
SVI
Krea/Text → VideoRuns on a laptop

Krea Releases Open-Source Real-Time Video Model

The new 14-billion-parameter model is a distilled, more efficient version of a larger foundation, designed for interactive video generation.

Oct 8, 2025
Text → Video
Krea Realtime Video
Tuesday, September 30, 2025

4 releases

inclusionAI/Any-to-AnyRuns on a laptop

inclusionAI Releases Ming-UniVision MoE Multimodal Model

The new 16-billion-parameter model uses a sparse Mixture-of-Experts design to efficiently handle 'any-to-any' data combinations, from text to images.

Sep 30, 2025
Any-to-AnyVision-Language
Ming-UniVision-16B-A3B
Qwen · Alibaba/Vision-LanguageMajor releaseConsumer GPU

Qwen Releases 30B MoE Vision Model, Qwen3-VL

The new open-source model from Alibaba uses a Mixture-of-Experts architecture to make its powerful vision-language capabilities more efficient to run.

Sep 30, 2025
Vision-LanguageAny-to-Any
Qwen3-VL-8B-Instruct
nineninesix/Text → SpeechRuns anywhere

Kani TTS 370M Offers Compact Multilingual Speech

Based on the Language-Free Modeling for Multilingual Text-To-Speech (LFM2) architecture, the new model offers an efficient solution for developers.

Sep 30, 2025
Text → Speech
Kani TTS 370M
chetwinlow1/Image → VideoRuns on a laptop

Ovi Syncs Audio and Video in New Open-Source Model

Built on the Wan2.2 architecture, this new 5-billion-parameter model generates short video clips from a single image and simultaneously creates synchronized audio.

Sep 30, 2025
Image → Video
Ovi
Monday, September 29, 2025

2 releases

Zhipu AI/Text / LLMMajor releaseMulti-GPU server

Zhipu AI Releases Open-Weight MoE Model GLM-4.6

The new Mixture-of-Experts model is available under a permissive MIT license and is optimized for complex reasoning and coding tasks.

Sep 29, 2025
Text / LLMReasoning
GLM-4.6
inclusionAI/Any-to-AnyRuns on a laptop

Ming-UniAudio Brings MoE to Unified Audio AI

A new 16-billion-parameter model from inclusionAI uses a Mixture-of-Experts architecture to handle a wide range of audio tasks efficiently.

Sep 29, 2025
Any-to-AnyText → Speech
Ming-UniAudio-16B-A3B
Friday, September 26, 2025

1 release

ByteDance/Image → Video

ByteDance Releases Lynx for Identity-Preserving Video

The new model from the TikTok parent company generates short video clips that maintain a person's likeness from a single reference image.

Sep 26, 2025
Image → Video
Lynx
Thursday, September 25, 2025

2 releases

Tencent/Text → ImageWorkstation GPU

Tencent Debuts HunyuanImage 3.0 with MoE Design

The new text-to-image generator from the Chinese tech giant uses a Mixture-of-Experts architecture for more efficient and detailed image creation.

Sep 25, 2025
Text → Image
HunyuanImage 3.0 Instruct
Tencent/Text → ImageMajor releaseWorkstation GPU

Tencent Releases HunyuanImage 3.0 Text-to-Image Model

The new text-to-image generator from the Chinese tech giant uses a Mixture-of-Experts architecture for improved efficiency and output quality.

Sep 25, 2025
Text → Image
HunyuanImage 3.0 Instruct
Monday, September 22, 2025

1 release

Qwen · Alibaba/Image EditingConsumer GPU

Qwen Releases Open-Source Instruction-Based Image Editor

The new model from Alibaba's Qwen team allows users to modify images using natural language prompts instead of complex tools or masks.

Sep 22, 2025
Image Editing
Qwen-Image-Edit-2509
Saturday, September 20, 2025

1 release

Qwen · Alibaba/Any-to-AnyMajor releaseConsumer GPU

Qwen3-Omni Arrives With Any-to-Any Multimodality

The new 30B Mixture-of-Experts model from Alibaba's Qwen team can process and generate content across text, image, and audio formats.

Sep 20, 2025
Any-to-AnyVision-Language
Qwen3-Omni-30B-A3B-Instruct
Thursday, September 18, 2025

1 release

Xiaomi/Any-to-AnyRuns on a laptop

Xiaomi's MiMo-Audio 7B Tackles Complex Speech Tasks

This new instruction-tuned model from Xiaomi can handle a flexible combination of audio and text inputs and outputs, from transcription to voice synthesis.

Sep 18, 2025
Any-to-AnyText → Speech
MiMo-Audio-7B-Instruct
Tuesday, September 16, 2025

1 release

OpenBMB/Text → SpeechRuns anywhere

OpenBMB Releases VoxCPM for Open Voice Synthesis

The new 500-million-parameter model offers high-quality text-to-speech and zero-shot voice cloning under a permissive license.

Sep 16, 2025
Text → Speech
VoxCPM-0.5B
Monday, September 15, 2025

3 releases

Qwen · Alibaba/Any-to-AnyConsumer GPU

Qwen Releases 'Thinking' Multimodal MoE Model

The new 30-billion-parameter Mixture-of-Experts model from Alibaba's Qwen team is designed to show its reasoning process for complex multimodal tasks.

Sep 15, 2025
Any-to-AnyReasoning
Qwen3-Omni-30B-A3B-Thinking
Qwen · Alibaba/Any-to-AnyConsumer GPU

Qwen Releases 30B Model for Audio Captioning

The new Mixture-of-Experts model from Alibaba is fine-tuned to generate detailed, multilingual descriptions for complex audio content.

Sep 15, 2025
Any-to-AnyText → Speech
Qwen3-Omni-30B-A3B-Captioner
neuphonic/Text → SpeechRuns anywhere

Neuphonic Releases NeuTTS Air for On-Device AI Speech

The new Apache 2.0 text-to-speech model is built on a Qwen2 architecture and optimized for local inference with GGUF support.

Sep 15, 2025
Text → Speech
NeuTTS Air
Thursday, September 11, 2025

1 release

moondream/Vision-LanguageRuns on a laptop

Moondream 3 Arrives in Preview Release

The next generation of the efficient, open-source vision-language model is now available for early testing and feedback.

Sep 11, 2025
Vision-Language
Moondream 3 (preview)
Wednesday, September 10, 2025

2 releases

ByteDance/Image → Video

ByteDance Releases HuMo for Human Video Generation

The new open-source model specializes in creating realistic videos of people, separating appearance from motion for greater control.

Sep 10, 2025
Image → Video
HuMo
Qwen · Alibaba/Text → VideoRuns on a laptop

Alibaba's Wan2.2 Adds Control to Open Video

The new 14-billion-parameter model from Alibaba's PAI team offers fine-grained control over video generation using inputs like sketches and depth maps.

Sep 10, 2025
Text → Video
Wan2.2-VACE-Fun-A14B
Tuesday, September 9, 2025

2 releases

Qwen · Alibaba/Text / LLMMajor releaseWorkstation GPU

Qwen Releases 80B Mixture-of-Experts Model

The new Qwen3-Next model from Alibaba combines a large parameter count with an efficient MoE architecture to balance performance and computational cost.

Sep 9, 2025
Text / LLM
Qwen3-Next-80B-A3B-Instruct
Alpha-VLLM/Any-to-AnyRuns on a laptop

Lumina-DiMOO: A Diffusion Model for Any-to-Any AI

This new open-source model uses a diffusion architecture instead of a typical transformer to generate and understand a mix of media types.

Sep 9, 2025
Any-to-AnyText → Image
Lumina-DiMOO
Monday, September 8, 2025

1 release

Tencent/Text → ImageRuns on a laptop

Tencent SRPO Fine-Tunes SDXL with Preference Optimization

The new text-to-image model uses a novel rejection sampling technique to align Stable Diffusion XL more closely with human aesthetic preferences.

Sep 8, 2025
Text → Image
SRPO
Friday, September 5, 2025

1 release

Tencent/Text → Image

Tencent Releases HunyuanImage 2.1 for Bilingual AI Art

The new text-to-image model from the Chinese tech giant is designed to understand both Chinese and English prompts at high resolutions.

Sep 5, 2025
Text → Image
HunyuanImage 2.1
Thursday, September 4, 2025

2 releases

Vibevoice/Text → SpeechRuns on a laptop

Microsoft Releases VibeVoice, a 7B Podcast TTS Model

The new 7-billion-parameter model is designed for generating long-form, multi-speaker audio in English and Chinese under a permissive MIT license.

Sep 4, 2025
Text → Speech
VibeVoice-7B
Aoi Ot/Text → SpeechRuns on a laptop

Microsoft Releases VibeVoice, a Podcast-Ready TTS Model

The new open-source model specializes in generating long-form, multi-speaker audio in both English and Mandarin, mimicking a natural podcast conversation.

Sep 4, 2025
Text → Speech
VibeVoice Large
Thursday, August 28, 2025

1 release

StepFun/Any-to-AnyRuns on a laptop

StepFun Releases Step-Audio 2 mini, a Unified Audio AI

The new open-source model handles both speech recognition and audio generation in a single, end-to-end architecture.

Aug 28, 2025
Any-to-AnyText → Speech
Step-Audio 2 mini
Wednesday, August 27, 2025

1 release

Tencent/Image → Video

Tencent's Voyager Model Turns Images into 3D Worlds

The new model from Tencent AI Lab generates temporally and spatially consistent video sequences from a single image, enabling virtual exploration of static scenes.

Aug 27, 2025
Image → VideoText → 3D
HunyuanWorld-Voyager
Monday, August 25, 2025

2 releases

Microsoft/Text → SpeechRuns anywhere

Microsoft Releases VibeVoice for Long-Form Audio

The new 1.5-billion-parameter text-to-speech model is designed to generate natural, multi-speaker audio for podcasts and other long-form content.

Aug 25, 2025
Text → Speech
VibeVoice-7B
Qwen · Alibaba/Image → VideoConsumer GPU

Alibaba Releases 14B Model for Audio-Driven Video

The new Wan2.2-S2V model takes a still image and a speech track to generate a realistic talking-head animation, available under a permissive license.

Aug 25, 2025
Image → Video
Wan2.2-S2V-14B
Sunday, August 24, 2025

1 release

OpenBMB/Vision-LanguageRuns on a laptop

OpenBMB Releases Compact Multimodal Model MiniCPM-V 4.5

The new vision-language model from the open-source research group demonstrates strong OCR and video understanding capabilities in a small package.

Aug 24, 2025
Vision-Language
MiniCPM-V 4.7 35B-A3B
Tuesday, August 19, 2025

1 release

DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases 671B MoE Model Under MIT License

The new DeepSeek-V3.1-Base is a massive 671-billion-parameter Mixture-of-Experts model designed for efficient, large-scale research and development.

Aug 19, 2025
Text / LLMReasoning
DeepSeek-V3.2
Sunday, August 17, 2025

1 release

Qwen · Alibaba/Image EditingMajor releaseConsumer GPU

Qwen Releases Open Model for Image Editing

The new open-source model from Alibaba lets users edit images with simple text commands in both English and Chinese.

Aug 17, 2025
Image Editing
Qwen-Image-Edit
Friday, August 15, 2025

1 release

NexaAI/Any-to-AnyRuns on a laptop

NexaAI Releases OmniNeural-4B for On-Device AI

The new 4-billion-parameter model is designed for 'any-to-any' multimodal tasks and optimized to run efficiently on mobile hardware.

Aug 15, 2025
Any-to-Any
OmniNeural-4B
Wednesday, August 13, 2025

1 release

Tencent/Image → Video

Tencent Releases Controllable Game Video Model

The new Hunyuan-GameCraft 1.0 is an open image-to-video model that generates interactive game-like scenes with precise camera control.

Aug 13, 2025
Image → Video
Hunyuan-GameCraft 1.0
Tuesday, August 12, 2025

1 release

FrancisRing/Image → VideoRuns on a laptop

StableAvatar Brings Open Source Talking Heads to Life

A new diffusion-based model from developer FrancisRing animates still images into talking avatars using only an audio track.

Aug 12, 2025
Image → Video
StableAvatar
Sunday, August 10, 2025

1 release

Zhipu AI/Vision-LanguageMajor releaseWorkstation GPU

Zhipu AI Releases Open Vision Model GLM-4.5V

The new Mixture-of-Experts model offers strong multimodal reasoning capabilities under a permissive MIT license.

Aug 10, 2025
Vision-LanguageReasoning
GLM-4.5V
Friday, August 8, 2025

1 release

Skywork/Image → VideoRuns anywhere

Skywork Releases Open 'World Model' for Playable Video

The new 1.3-billion-parameter model functions as an interactive 'world model,' generating controllable video scenes from a single static image.

Aug 8, 2025
Image → Video
Matrix-Game 2.0
Wednesday, August 6, 2025

1 release

Meta AI/EmbeddingsRuns anywhere

Meta Releases DINOv3 ViT-L/16 Vision Backbone

The self-supervised feature extractor arrives on Hugging Face as a general-purpose backbone for downstream vision tasks.

Aug 6, 2025
Embeddings
DINOv3 ViT-L/16
Tuesday, August 5, 2025

1 release

Google DeepMind/Text / LLMRuns anywhere

Google Releases Gemma 3 270M for On-Device AI

The new ultra-compact model from DeepMind is designed for efficient performance in resource-constrained environments like mobile and web.

Aug 5, 2025
Text / LLM
Gemma 3 270M
Monday, August 4, 2025

4 releases

OpenAI/ReasoningMajor releaseRuns on a laptop

OpenAI Releases 21B Open-Weight MoE Model

The new `gpt-oss-20b` is an Apache 2.0-licensed Mixture-of-Experts model designed to run efficiently on consumer-grade hardware.

Aug 4, 2025
ReasoningText / LLM
gpt-oss-20b
OpenAI/ReasoningMajor releaseWorkstation GPU

OpenAI Releases Its First Open-Source MoE Model

The new 117-billion-parameter `gpt-oss-120b` is a Mixture-of-Experts model focused on reasoning, released under a permissive Apache 2.0 license.

Aug 4, 2025
ReasoningText / LLM
gpt-oss-20b
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Canary 1B v2 Multilingual Speech Model

The new 1-billion-parameter model handles both transcription and translation across five languages using the company's efficient FastConformer architecture.

Aug 4, 2025
Speech → Text
Canary 1B v2
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases 600M Parakeet for Speech Recognition

The new FastConformer model uses a specialized training technique to improve transcription accuracy in noisy, real-world environments.

Aug 4, 2025
Speech → Text
Parakeet TDT 0.6B v3
Saturday, August 2, 2025

1 release

Qwen · Alibaba/Text → ImageMajor releaseConsumer GPU

Qwen releases open model for text-in-image generation

The new Apache 2.0 diffusion model from Alibaba's Qwen team focuses on accurately rendering both English and Chinese characters within generated images.

Aug 2, 2025
Text → Image
Qwen-Image
Thursday, July 31, 2025

1 release

Qwen · Alibaba/CodeConsumer GPU

Qwen Releases Compact 30B MoE for Coding Agents

The new Apache 2.0 model from Alibaba's Qwen team uses a Mixture-of-Experts architecture to deliver strong performance with only 3B active parameters.

Jul 31, 2025
CodeText / LLM
Qwen3-Coder-30B-A3B-Instruct
Wednesday, July 30, 2025

1 release

rednote-hilab/Vision-LanguageRuns anywhere

New VLM `dots.ocr` Takes on Complex Documents

The new 3B-parameter model from rednote-hilab uses a vision-language approach to parse tables, layouts, and even mathematical formulas.

Jul 30, 2025
Vision-Language
dots.ocr
Tuesday, July 29, 2025

1 release

Skywork/Any-to-AnyRuns anywhere

Skywork Releases UniPic, a Unified 1.5B Vision Model

The new autoregressive model from the Chinese AI lab can understand, generate, and edit images within a single, compact framework.

Jul 29, 2025
Any-to-AnyText → Image
Skywork-UniPic-1.5B
Monday, July 28, 2025

3 releases

Qwen · Alibaba/Image → VideoMajor releaseRuns on a laptop

Alibaba Releases Wan2.2, a 14B MoE Video Model

The new open-source diffusion model from the team behind Qwen uses a Mixture-of-Experts architecture to animate still images.

Jul 28, 2025
Image → Video
Wan2.2-I2V-A14B
Tencent/Text → VideoRuns on a laptop

Tencent Releases Wan2.2, a 14B MoE Video Model

The new Apache 2.0-licensed generator uses a Mixture-of-Experts architecture and is available in the popular Diffusers library format for easier integration.

Jul 28, 2025
Text → Video
Wan2.2 T2V A14B
Qwen · Alibaba/Text → VideoRuns on a laptop

Qwen Releases Wan2.2, a 5B Open-Source Video Model

The new Apache 2.0 licensed model from Alibaba's team generates video from either text prompts or still images, offering a unified approach in a compact package.

Jul 28, 2025
Text → VideoImage → Video
Wan2.2-TI2V-5B
Thursday, July 24, 2025

2 releases

Qwen · Alibaba/Text → VideoRuns on a laptop

Qwen Unveils Wan2.2, a 14B Open Text-to-Video Model

The new Apache 2.0-licensed model from Alibaba's team uses a Mixture-of-Experts architecture for efficient, high-quality video generation.

Jul 24, 2025
Text → Video
Wan2.2 T2V A14B
Qwen · Alibaba/Image → VideoRuns on a laptop

Qwen Releases Wan2.2, a 14B Image-to-Video Model

The new 14-billion parameter model from Alibaba's AI team uses a Mixture-of-Experts design and is available under the permissive Apache 2.0 license.

Jul 24, 2025
Image → Video
Wan2.2-I2V-A14B
Tuesday, July 22, 2025

1 release

Qwen · Alibaba/CodeMajor releaseMulti-GPU server

Qwen Releases 480B Open-Source Model for Code Agents

The new flagship coding model from Alibaba's Qwen team uses a massive Mixture-of-Experts architecture and is released under a permissive Apache-2.0 license.

Jul 22, 2025
CodeText / LLM
Qwen3-Coder-30B-A3B-Instruct
Sunday, July 20, 2025

1 release

Zhipu AI/Text / LLMMajor releaseMulti-GPU server

Z.ai Releases 355B Parameter GLM-4.5 Under MIT License

The new Mixture-of-Experts model combines massive scale with a fully permissive license, targeting complex reasoning and agentic applications.

Jul 20, 2025
ReasoningText / LLM
GLM-4.6
Friday, July 18, 2025

1 release

Qwen · Alibaba/Text → VideoMajor releaseRuns on a laptop

Qwen Releases Wan 2.2, a 5B Open Video AI Model

The new Apache 2.0 licensed model from Alibaba's team can generate video from both text and image prompts, adding a powerful new tool to the open-source creative ecosystem.

Jul 18, 2025
Text → VideoImage → Video
Wan2.2-TI2V-5B
Wednesday, July 16, 2025

1 release

HiDream.ai/Image EditingConsumer GPU

HiDream.ai Releases 17B Open Image Editing Model

The new MIT-licensed model, HiDream-E1.1, allows for complex image modifications by following natural language instructions.

Jul 16, 2025
Image Editing
HiDream-E1.1
Tuesday, July 15, 2025

1 release

inclusionAI/Any-to-AnyRuns on a laptop

Ming-Lite-Omni 1.5 Brings Any-to-Any Modality to Open Source

The new MIT-licensed model from inclusionAI can process and generate a mix of text, images, audio, and video, pushing the boundaries of open multimodal AI.

Jul 15, 2025
Any-to-Any
Ming-Lite-Omni 1.5
Monday, July 14, 2025

2 releases

RaphaelLiu/Image → VideoRuns on a laptop

Pusa V1: A New Open Model for Image-to-Video Animation

Based on the Wan2.1 architecture, this new 14B parameter model offers fine-grained control over video generation from still images and text.

Jul 14, 2025
Image → VideoText → Video
Pusa V1
T-Tech/Speech → TextRuns anywhere

T-Tech Releases T-one for Russian Speech Recognition

The new streaming Conformer model from the Russian digital bank is optimized for real-time transcription of telephone conversations.

Jul 14, 2025
Speech → Text
T-one
Friday, July 11, 2025

1 release

Moonshot AI/Vision-LanguageMajor releaseDatacenter

Moonshot AI Releases Trillion-Parameter Kimi-K2 Model

The new Mixture-of-Experts model brings massive scale to the open-weights community, focusing on complex reasoning and coding tasks with a 128K context window.

Jul 11, 2025
Text / LLMReasoning
Kimi K2.6
Monday, July 7, 2025

1 release

Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

Black Forest Labs Releases FLUX.1 Krea Image Model

The new 12-billion-parameter model, tuned by creative AI platform Krea, focuses on high-quality aesthetic output and prompt fidelity.

Jul 7, 2025
Text → Image
FLUX.1 Krea [dev]
Wednesday, July 2, 2025

1 release

ByteDance/Any-to-AnyRuns on a laptop

ByteDance Releases Tar-7B for 'Any-to-Any' Multimodality

The new 7-billion-parameter model from the company's SEED team can process and generate a mix of text, images, audio, and video in a single unified framework.

Jul 2, 2025
Any-to-Any
Tar-7B
Tuesday, July 1, 2025

1 release

Bosonai/Text → SpeechRuns anywhere

Boson AI Releases Higgs Audio v2 for Expressive TTS

The new 3-billion-parameter model focuses on generating expressive, multilingual speech and is fully open for commercial use under an Apache 2.0 license.

Jul 1, 2025
Text → Speech
Higgs Audio v2 (3B)
Monday, June 30, 2025

1 release

Kyutai/Text → SpeechRuns anywhere

Kyutai Releases 1.6B Bilingual TTS Model

The French AI lab's new open-source model generates streaming audio in English and French under a permissive license.

Jun 30, 2025
Text → Speech
Kyutai TTS 1.6B (en/fr)
Saturday, June 28, 2025

2 releases

Zhipu AI/Vision-LanguageRuns on a laptop

Zhipu AI Open-Sources 9B Vision Model with 'Thinking' Mode

The new GLM-4.1V-9B-Thinking model makes its vision and chain-of-thought reasoning capabilities available under a permissive MIT license.

Jun 28, 2025
Vision-LanguageReasoning
GLM-4.1V-9B-Thinking
AIDC-AI/Any-to-AnyRuns on a laptop

Ovis-U1-3B Unifies Image Understanding and Generation

The new 3-billion-parameter model from AIDC-AI combines vision-language understanding and image generation into a single 'any-to-any' framework.

Jun 28, 2025
Any-to-AnyVision-Language
Ovis-U1-3B
Thursday, June 26, 2025

1 release

NVIDIA/Speech → TextRuns anywhere

NVIDIA Fuses LLM and ASR in Canary-Qwen 2.5B Model

The 2.5 billion-parameter speech model combines a FastConformer encoder with a Qwen LLM decoder, a hybrid approach to transcription.

Jun 26, 2025
Speech → Text
Canary-Qwen 2.5B
Tuesday, June 24, 2025

1 release

Maya Research/Text → SpeechRuns on a laptop

Veena TTS Model Targets Indian Languages with Llama Base

Maya Research has released a 3-billion-parameter model designed to generate natural-sounding speech in Hindi and English.

Jun 24, 2025
Text → Speech
Veena
Monday, June 23, 2025

1 release

FreedomIntelligence/Any-to-AnyRuns on a laptop

Janus-4o-7B Adds Image Generation to 7B Multimodal AI

The new 7-billion-parameter model from FreedomIntelligence can process various inputs and generate or edit images based on text prompts.

Jun 23, 2025
Any-to-AnyText → Image
Janus-4o-7B
Tuesday, April 15, 2025

1 release

Pyannote/Speech → Text

pyannote ships community-1 diarization pipeline

A new community edition of pyannote's open-source speaker diarization model lands on Hugging Face, targeting the "who spoke when" problem.

Apr 15, 2025
Speech → Text
pyannote speaker-diarization-community-1
Wednesday, September 25, 2024

1 release

Unknown/Text → ImageRuns on a laptop

Illustrious-XL v0.1 Arrives as Anime Image Base

A 3.5B-parameter SDXL derivative aims to become the go-to foundation for anime-style text-to-image fine-tunes.

Sep 25, 2024
Text → Image
Friday, August 2, 2024

1 release

Black Forest Labs/Text → ImageMajor releaseRuns on a laptop

FLUX.1 Dev Becomes the Open-Weight Base to Beat

Black Forest Labs' 12B rectified-flow model has quietly emerged as the default foundation for open image generation.

Aug 2, 2024
Text → Image
FLUX.1 Dev